study guide · Kubernetes basics in 8 stages + bonus
Kubernetes explained
through the F1 lens.
This guide teaches Kubernetes from scratch, in eight stages and a bonus, with every exercise running on a Minikube cluster on your own machine. You start by understanding why an orchestrator exists and how to talk to the cluster through kubectl; then you study the anatomy of the cluster and Pods, Services and ConfigMaps, ReplicaSets and Deployments, persistent volumes, probes and the HPA. In the bonus stage, you put these pieces together in a deployment of a real Docker Hub image and decide which of them the app needs and which stay out. Before the stages, the next section introduces the F1 lens of the guide: a general comparison that shows the same system working inside a Formula 1 team.
Each stage depends only on what was explained before it and includes a small exercise that proves you understood. Kubernetes is learned by running things and by making mistakes on purpose, so do not skip the "Hands-on" blocks.
How to use this guide: keep a terminal open next to the text. All commands were designed for Minikube, which you install in Stage 01. When an example shows the expected output, compare it with yours. Pod names, IPs and timings will vary; the structure of the output is what matters. When an output is shortened, it is marked with (...).
Organize your files by stage. Create one folder for each stage (etapa03/, etapa04/, etapa05/ and so on) and save the YAMLs inside it. This is necessary because the name deployment.yaml repeats in Stages 05, 08 and 09, and service.yaml and hpa.yaml repeat in Stages 08 and 09, and working in a single folder would make one file overwrite the previous one. Run the commands from inside the stage folder. At the end of each stage there is a cleanup step; run it before moving on, so that old objects do not interfere with the following exercises.
The F1 lens of this guide
An F1 team on a GP weekend
A Formula 1 team arrives at a Grand Prix weekend with two cars, a garage in the pit lane and a few dozen people with clearly separated roles. On the pit wall (the gantry facing the track) sit the strategist and the engineers who decide: what each car should do, when to stop, which target to chase. In the garage are the mechanics, organized in one crew per car, each with a chief mechanic. They do not decide strategy: they assemble, adjust and repair the cars according to what the pit wall defined. The cars, on the track, are the units that actually do the work. The regulations limit each team to two cars per race, and that limit will show up a few times as the point where the comparison stops holding.
Nobody on the pit wall touches the car. Information flows through two channels: the team radio and intercom, which carry orders and questions, and the telemetry, hundreds of sensors that continuously transmit the state of each car. To enter that channel you have to be on the team's frequency and hold a credential. Everything the team knows and decides is recorded on the data servers: the weekend plan, the versions of each part, the history of each car. Whoever wants to know how a car is doing consults that record through the official channel, instead of walking to the garage to ask.
The car itself is described by a specification sheet: chassis, power unit (the car's engine, which combines the combustion engine and the electrical part that recovers and returns energy), aerodynamic package, each component with its version. Two cars assembled from the same sheet are equivalent, and a chassis destroyed in a crash is replaced by another one assembled from the same sheet. The chassis is disposable; the specification is what remains. Separate from it there is the parameter sheet (engine maps, energy modes, targets), which changes the car's behavior without swapping any part. What the radio and the timing call is the car's race number, never the serial number of the chassis underneath it.
It is the same division of labor that Kubernetes makes: the control plane decides like the pit wall, the nodes execute like the garages, the Pods run like the cars, each Pod comes out of a manifest the way the car comes out of the specification sheet, and everything that is known and ordered goes through a single channel, like the radio and the telemetry. In this guide, you take the place of the person who writes the plan and talks to the pit wall over the radio.
One fixed rule holds for the whole guide: each assembled chassis is a Pod. Swapping the chassis means creating a new Pod, with another serial number (another IP), while the race number (the Service) stays the same. Restarting a system that shut down inside the car, without swapping the chassis, is restarting a container inside the same Pod.
The terms in plain words
43
The table below translates each technical term in the guide into an everyday idea, with no F1 and no jargon. You do not need to memorize it; come back to it whenever a term shows up in the text.
| Technical term | In plain words |
|---|---|
| Cluster | A group of computers working together as if they were one. |
| Control plane (master node) | The management: it decides what runs on each computer and checks that everything matches what was asked, but it does not do the work itself. |
| Worker node | One of the computers that actually does the work. |
| API Server | The service desk: every request and every question goes through it. |
| kubectl | The app you use to talk to the service desk. |
| kubeconfig | The address of the service desk and your access badge, kept in a file. |
| Imperative and declarative | Giving an order on the spot ("do this now") or writing down how things should end up. |
| Events | The time-stamped history of what happened to each item. |
| etcd | The official notebook where everything that was requested, and the current state of each thing, is written down. |
| kubelet | The supervisor on each computer, who looks after what runs there. |
| kube-proxy | The contact list on each computer, which knows where to forward each call. |
| Virtual machine | A whole computer simulated inside another one, with its own operating system: complete, but heavy. |
| Host kernel | The core of the computer's system, shared by every program running on it. |
| Container image | A sealed recipe with a version number: followed anywhere, it always gives the same result. |
| Container | The program prepared from the recipe, running apart from the others; it can be restarted without touching the rest. |
| Pod | The smallest box the system manages: one or more programs that always travel together. If the box is replaced, it is a different box, with a different address. |
| Second container in the Pod | A helper program inside the same box, like a recorder that logs what the main one does. |
| Pod IP | The box's address, which changes when the box is replaced. |
| Namespace | Separate folders inside the same system, each with its own list of items. |
| Label | A sticker on an item, used to find all items of the same kind at once. |
| Annotation | A sticky note on an item, written for people to read; it is not used for searching. |
| YAML manifest | The filled-in form that describes what you want, kept so it can be reused. |
| Desired state | A standing request, like "always keep 3 running", that the system works on its own to maintain. |
| Minikube | A workbench version of the system that runs on your own computer for studying. |
| Service | A fixed service number that forwards the call to whoever is available, even when the people change. |
| ClusterIP, NodePort, LoadBalancer | An internal-only extension; the same extension opened on every computer for outside callers; a published public number. |
| ConfigMap | The settings sheet kept apart from the program, read when the program starts. |
| Secret | The same kind of sheet, for passwords and keys, kept with more care. |
| ReplicaSet | The rule "always N copies running": if one disappears, another is created. |
| Deployment | The one in charge of versions: it swaps versions carefully and keeps the history of earlier ones. |
| Rolling update | Swapping the version one copy at a time, without closing the service. |
| Rollback | Going back to the previous version, the one that worked. |
| emptyDir | A temporary scratch pad, thrown away together with the box. |
| hostPath | A drawer in one specific computer: it is only useful to whoever is on that computer. |
| PVC | The request for space to store data ("I need 1 GB"). |
| PV | The actual storage space that fulfills that request. |
| StorageClass | The menu of storage types that can be created when someone asks. |
| restartPolicy | The rule that restarts, on its own, a program that crashed, in the same box. |
| Probes | Routine questions asked every few seconds to find out whether the program is fine. |
| Liveness, readiness, startup | "Are you alive?" (if not, restart); "can you serve?" (if not, stay out of the service); "have you finished starting?" (until then, the other questions wait). |
| HPA | Automatic adjustment of the number of copies to match demand, always between a minimum and a maximum. |
| metrics-server | The usage meter that feeds that adjustment; without it, there are no numbers to decide with. |
| resources.requests | The declared reservation of resources; usage percentages are calculated from it. |
Where the comparison stops
9
The comparison helps fix the division of roles, but it is not a perfect equivalence. These are the points where F1 stops applying for each stage:
- Stage 01: a team replaces a car in hours, between sessions, and the regulations fix the number at two cars; Kubernetes creates a new Pod in seconds, at any moment, and the limit on quantity is only what the cluster can handle.
- Stage 02: the F1 radio is voice, interpreted by people; the Kubernetes API is a rigid HTTP protocol, in which every request has a method, a path and a response code, with no room for interpretation.
- Stage 03: the systems of a car are physically integrated and designed together, while the containers of a Pod are independent processes that can be swapped one by one in the specification without touching the others.
- Stage 04: a race number points to a single car, while the Service distributes requests among several replicas at the same time; load balancing has no equivalent in F1.
- Stage 05: in F1, a car is replaced between sessions, in hours, and the regulations limit the team to two cars; the ReplicaSet replaces in seconds, at any moment, and keeps whatever number of replicas is declared.
- Stage 06: in F1, the car's data is transmitted or downloaded to the servers, that is, a copy exists; the PVC copies nothing, the Pod writes directly to the external volume, and if the PVC is deleted with the
Deletepolicy the data goes with it. - Stage 07: in F1, restarting a system on track involves the driver and almost always costs the session; in Kubernetes, the kubelet restarts the container in seconds, with nobody's intervention, and the Pod remains the same Pod, with the RESTARTS counter going up.
- Stage 08: at a GP the team races with exactly two cars, by regulation; the HPA, which adds or removes replicas according to load, only has a parallel in an imaginary operation with no limit on cars, and this is the stage where the comparison strays furthest from real F1.
- Stage 09: in an F1 car the driver changes maps and modes from the steering wheel in the middle of a lap, and the new value applies at once; in Kubernetes, an environment variable read from a ConfigMap only changes when the Pod is recreated.
Stage 01 motivation + setup
Why Kubernetes exists
The problem
Picture the e-commerce site of a mid-sized company. For eleven months it receives a predictable volume of visits. In the week of Black Friday, traffic multiplies several times over. If you size the servers for everyday traffic, the site goes down at the peak. If you size them for the peak, you pay for idle machines all year. The infrastructure needs to grow and shrink with demand.
There is a second, less visible problem. The developer runs the application on their own machine, QA tests on another one, and production is a third. Any difference in library version, operating system or configuration produces the classic "it works on my machine". Keeping dev, test and production identical by hand is a constant source of bugs.
Every software project runs into these two problems: keeping environments equal and scaling when demand changes. Kubernetes automates the solution to both.
The concept
The piece common to both solutions is the container.
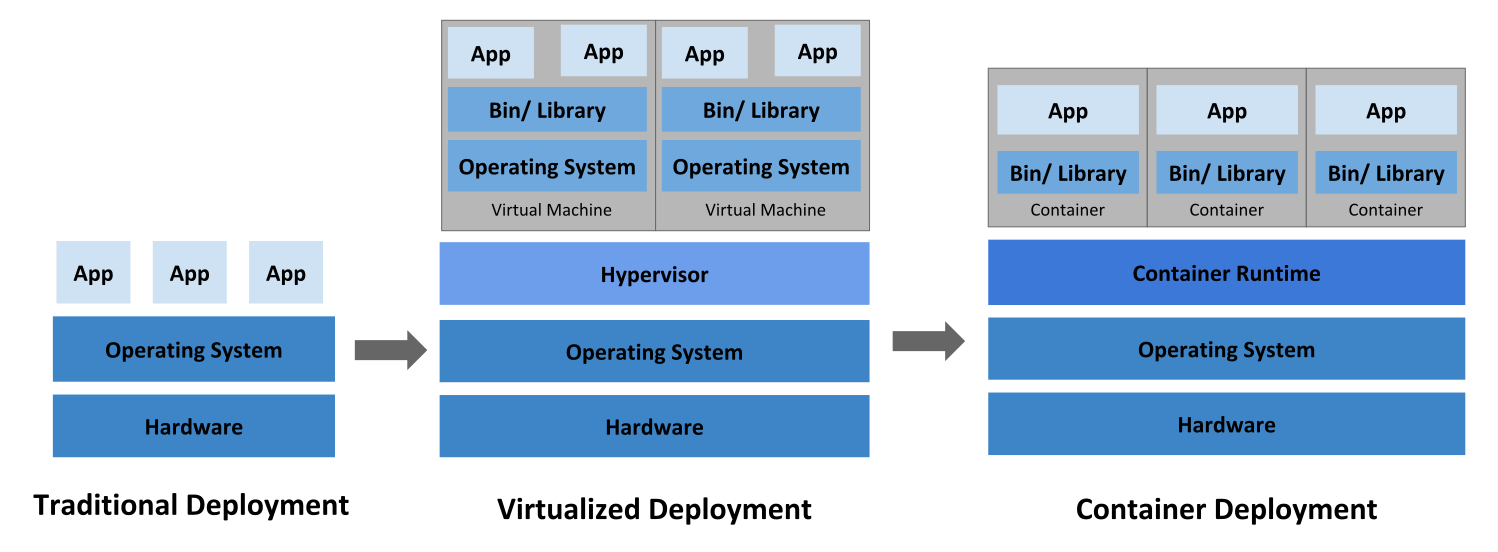
A virtual machine (VM) carries virtualized hardware and a complete operating system: it takes up gigabytes and takes minutes to start. A container shares the kernel of the host operating system and carries only the files, binaries and libraries the app needs: it takes up megabytes and starts in seconds. A container image packages that whole environment and can be run identically anywhere, which solves the "it works on my machine" problem.
Containers solve the environment problem and create another one. With dozens or hundreds of them, someone has to create them, destroy them, watch the health of each one and recreate whatever fails. Doing that manually does not scale. Kubernetes (K8s) is the orchestrator that takes over these tasks.
The central idea of Kubernetes is the desired state. You do not run a sequence of orders ("start this container, then that one"). You declare the result you want ("I want 3 copies of this application running") and Kubernetes continuously compares what exists with what was declared, correcting any difference. If one of the copies disappears at 3 a.m. (the Pod is deleted or the node it was running on goes down), the cluster notices that there are 2 copies instead of 3 and creates the missing one, without anyone waking up. When what fails is only the process inside the container, another mechanism reacts, one you will clearly tell apart in Stage 07.
Key concepts
Container
an isolated process that shares the host kernel and carries only what the app needs. Much lighter than a VM.
Image
an immutable package with the app's environment. The container is an image in execution.
Horizontal scaling
more copies of the application sharing the load (this is what K8s automates). Vertical scaling is giving more CPU and RAM to the same machine.
Cluster and node
K8s organizes machines (nodes) into a cluster, which is treated as a single platform.
Pod
the group of containers that K8s manages as a unit. It is the smallest managed unit (details in Stage 03).
Namespace
a logical separation of resources inside the cluster. When you indicate none, the namespace used is default.
kubectl
a command-line tool that talks to the cluster's REST API (details in Stage 02).
Minikube
a 1-node K8s cluster running on your machine. Built for study, it is the lab of this guide.
Desired state
you declare what you want, and K8s makes it happen and keeps it that way. If something goes down, it recreates it.
Setting up the lab
# 1. Install Docker Desktop (docker.com). On Linux, use Docker# Engine (docs.docker.com/engine/install). Confirm:$ docker -vDocker version 27.x# 2. Install kubectl (kubernetes.io/docs/tasks/tools) and confirm.# Use --client: there is no cluster yet, so only the client# version can be queried (without --client, kubectl would try to talk# to a nonexistent server and print a connection error)$ kubectl version --clientClient Version: v1.30.xKustomize Version: v5.x# 3. Install Minikube (minikube.sigs.k8s.io/docs/start) and start the cluster:$ minikube start😄 minikube v1.33 on Windows 11✨ Using the docker driver🏄 Done! kubectl is now configured to use "minikube"# 4. Confirm the cluster is up:$ kubectl get nodesNAME STATUS ROLES AGE VERSIONminikube Ready control-plane 1m v1.30.x# 5. Empty cluster = success:$ kubectl get podsNo resources found in default namespace.# 6. Now that the cluster exists, the full version shows client and server:$ kubectl version --output=yamlclientVersion:(...)serverVersion:(...)
The first run of minikube start downloads the cluster image and takes a few minutes. This is normal.
Essential commands for this stage
Hands-on
The smallest possible exercise: prove that the lab is alive.
- Run
minikube startand wait for the "Done!". - Run
kubectl get nodes. Observe theminikubenode withSTATUS Ready. IfNotReadyappears, wait 1 minute and repeat. - Run
kubectl get pods. ObserveNo resources found in default namespace.An empty, ready cluster is the starting point of the next stage. - Bonus: run
minikube stopand thenkubectl get nodes. Observe the connection error message (the cluster does not respond). Start it again withminikube start. Now you know what "cluster down" looks like in the terminal.
Tip: If minikube start fails, the most common cause is Docker Desktop not being open. On Linux, the equivalent is the stopped service: sudo systemctl start docker. Start Docker first and try again.
Takeaway: A container is a light, replicable environment; Kubernetes maintains the desired state of those containers: you declare what you want, and it guarantees it.
Stage 02 command line + API
kubectl and the API, how you command the cluster
The problem
The cluster is up (Stage 01), but you still do not know how to talk to it. Imagine that the checkout service stopped responding at 2 a.m. and you are on call. You need to find out which pods exist, what state they are in, what the app is printing and, if necessary, get inside the container to investigate. None of this can depend on physical access to the machine where the container runs.
The concept
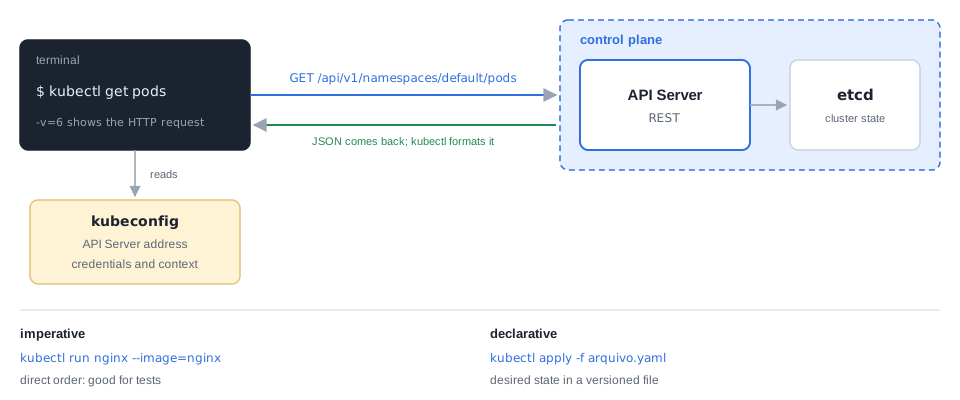
Everything in Kubernetes goes through the REST API of the master node (the *control plane*). kubectl is the client of that API: each command you type becomes an HTTP request (GET, POST, PUT or DELETE) against the cluster.
The path of a command is this:
- You type
kubectl get pods. - kubectl reads the kubeconfig file, which holds the API Server address, the credentials and the current cluster context. Minikube fills in this file by itself on
minikube start. - kubectl sends a
GETto the API Server (for thedefaultnamespace, the path is/api/v1/namespaces/default/pods). - The response comes back and kubectl formats it in the terminal.
The API is divided into groups. The "core" group holds the fundamental resources (pods, services, replicasets); other groups handle security, storage and autoscaling. Since it is plain REST, any language (Python, Go, Java, C#) can call it, which opens room for automation.
There are two ways of working with kubectl:
- Imperative: you give the direct order, as in
kubectl run nginx --image=nginx. It is fast and good for tests. - Declarative: you write a YAML file that describes the desired state and run
kubectl apply -f file.yaml. It is the dominant mode in real projects, because the file can be versioned in Git, reviewed and reapplied.
In this guide we start with the imperative way, which is faster to learn, and move to the declarative way in Stage 03.
-v=6 shows the request that was made.Diagram: made for this guideKey concepts
API Server
the cluster's front door; it receives every request, validates it and executes it.
kubeconfig
a file with the cluster address, credentials and current context.
Imperative vs. declarative
giving step-by-step orders versus describing the final state.
Events
history of events for an object (image pulled, container created, failure). It appears at the end of describe.
Everyday verbs
- get: queries resources and the status of each one (get pods, get svc, get nodes). - create / run / apply: create resources. run creates an imperative pod; apply -f applies a YAML. - delete: removes. Be careful, it can affect whoever depends on the resource. - describe: shows the configuration and the Events section. It is the first stop when something gets stuck. - logs: shows what the container is printing. It is the main source of information when debugging. - exec: runs a command inside the container, for example a shell.
The life cycle of a Pod
# Creates a pod named "nginx" from the nginx:1.14.2 image on Docker Hub$ kubectl run nginx --image=nginx:1.14.2 --port=80pod/nginx created# Follow until the status becomes Running (the first state is ContainerCreating)$ kubectl get podsNAME READY STATUS RESTARTS AGEnginx 1/1 Running 0 30s# Details + events (see the "Pulling image" line in the Events section)$ kubectl describe pod nginxName: nginx(...)Events:Type Reason Age From MessageNormal Scheduled 35s default-scheduler Successfully assigned default/nginx to minikubeNormal Pulling 34s kubelet Pulling image "nginx:1.14.2"Normal Pulled 20s kubelet Successfully pulled image "nginx:1.14.2"Normal Created 20s kubelet Created container nginxNormal Started 20s kubelet Started container nginx# What the container is printing (nginx writes the access log to standard# output, so it only shows lines after requests arrive)$ kubectl logs nginx# Opens a shell inside the container (type "exit" to leave).# Note: after this command you are INSIDE the container and the prompt# becomes "# ". The lines below that start with "# " (ls and exit) are not# comments: they are commands typed in the container's shell.$ kubectl exec -it nginx -- /bin/sh# ls /usr/share/nginx/html50x.html index.html# exit# Back in your terminal (prompt "$"). Cleanup:$ kubectl delete pod nginxpod "nginx" deleted
If the status stays at ImagePullBackOff, the cluster could not download the image. Check the image name and tag and your internet connection. To see the HTTP request behind a command, raise kubectl's log level. The exact format changes from version to version, but you should find a line with the method, the API path and the status:
Essential commands for this stage
Hands-on
Run the complete cycle and provoke your first error on purpose.
- Run the sequence from the example (
run,get,describe,logs,delete). Observe theEventssection ofdescribe: the linesPulling image,Created containerandStarted containertell the pod's story in order. - Create a deliberately broken pod:
kubectl run quebrado --image=nginx:versao-que-nao-existe. - Run
kubectl get pods. Observe the statusErrImagePull, which soon becomesImagePullBackOff. - Run
kubectl describe pod quebrado. Observe in the Events the message saying the image was not found. You have just practiced the real debugging flow. - Run
kubectl get pods -v=6and observe the line withGET .../api/v1/namespaces/default/pods. This is the command translated into HTTP. - Clean up:
kubectl delete pod quebrado.
Tip: Memorize the debugging flow: get pods (what is the status?), then describe pod (what do the Events say?), then logs (what does the app say?). This sequence solves most problems.
Takeaway: Everything in K8s is a call to the REST API, kubectl is the client of that API, and when something gets stuck the path is always get, describe, logs.
Stage 03 architecture + labels
The anatomy of the cluster and its smallest unit, the Pod
The problem
In Stage 02 you created a pod with an imperative command. It works, but there are two gaps. First, you do not know what exactly was created or where inside the cluster. Second, if tomorrow you need to recreate that same pod in another environment, you will only have your memory of the command you typed. On top of that, imagine a team with 40 pods in the same cluster (checkout, catalog, payment, search). How do you list only the checkout ones? We need to understand the pieces of the cluster, describe objects in versionable files and group them by criteria that Kubernetes itself can use.
The concept
A cluster is a group of machines (nodes) working together, with well-defined roles:
- The master node (control plane) manages the cluster and decides where to run the Pods.
- The worker nodes run the Pods and the other resources.
- etcd is the distributed database that stores the configuration and state of everything in the cluster.
- The kubelet is the agent that runs on each node and manages the Pods of that node.
- kube-proxy forwards network traffic to the right Pod.
- The API Server is the front door, through which everything kubectl does passes (Stage 02).
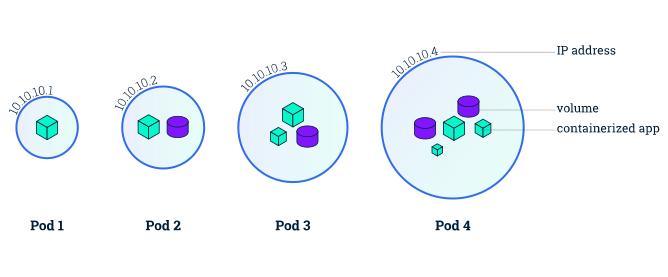
The Pod is the smallest unit that Kubernetes manages: an envelope with one or more containers that share network and storage. Four facts about Pods:
- A Pod represents a running process and can have more than one container, all sharing the same IP and the same volumes.
- Pods are ephemeral. They are born and die all the time, and you must never count on a specific Pod existing tomorrow. This sentence is the root of Stages 04, 05 and 06.
- Each Pod receives an internal cluster IP.
- Pods are described in YAML.
To organize many objects there are labels and annotations. Labels are key-value pairs used to identify and select objects: it is by label that a Service finds its Pods (Stage 04) and that a Deployment knows which Pods are its own (Stage 05). Annotations are free-form metadata (author, documentation link, audit data) that do not take part in selection; they are for people and tools to read. This difference is a classic exam question.

Key concepts
Master node
manages the cluster and decides where to run the Pods.
Worker node
runs the Pods and other resources.
etcd
distributed database with the cluster's configuration and state.
kubelet
agent on each node that manages the local Pods.
kube-proxy
forwards network traffic to the right Pods.
API Server
front door for everything kubectl does.
Pod
one or more containers with shared network and volumes; ephemeral.
Label
key-value pair to identify and select objects.
Annotation
free-form metadata for documentation, with no role in selection.
Manifest
YAML file that describes an object. Every manifest has apiVersion, kind, metadata and spec.
The first YAML
Create the etapa03/ folder and save the manifest below in it as meu-pod.yaml. This is the skeleton you need to know by heart.
apiVersion: v1 # K8s API version for this objectkind: Pod # the TYPE of object createdmetadata: # data ABOUT the objectname: meu-podlabels: # labels: key-value pairs to SELECTapp: myappambiente: estudoannotations: # annotations: free-form metadata (docs)autor: "Davi Gomes"spec: # the SPECIFICATION: what runs insidecontainers:- name: meu-containerimage: nginx:1.14.2ports:- containerPort: 80
Every K8s object follows this skeleton: apiVersion + kind + metadata + spec. What changes from one object to another is the value of kind and the content of spec; the rest is always the same. Whoever masters this skeleton can read any manifest.
Essential commands for this stage
Hands-on
- Save the YAML above as
etapa03/meu-pod.yamland apply it withkubectl apply -f meu-pod.yaml. - Run
kubectl get pods --show-labels. Observe the two labels in the last column. - Run
kubectl get pods -l app=myappand thenkubectl get pods -l app=outra-coisa. Observe: the first finds the pod, the second answersNo resources found in default namespace.This is the selection mechanism in action. - Add a label on the fly with
kubectl label pod meu-pod time=devopsand confirm with--show-labels. - Do not delete the pod now: it will be the target of the Service in the next stage, and its cleanup is at the end of Stage 04. If you deleted it, apply the YAML again. This is the advantage of the declarative way: the file recreates the identical object.
Tip: Labels are operational selection (K8s uses them). Annotations are documentation (people use them). To record the author of a Pod, use an annotation; to group the Pods of an application, use a label.
Takeaway: Every K8s object is apiVersion + kind + metadata + spec, and labels are the mechanism by which everything in the cluster finds everything else.
Stage 04 networking + config
Services and ConfigMaps, a fixed address and external configuration
The problem
From Stage 03, Pods are ephemeral and each new Pod is born with a different IP. Now imagine the front end of an e-commerce site calling the orders API. Today the API is at IP 10.244.0.5. Tomorrow the Pod dies, is recreated and becomes 10.244.0.9. If the front end has the old IP written in its code, it breaks at every recreation. How does anyone talk to Pods reliably if the address keeps changing?
There is a second problem. Every service needs configuration (ports, URLs of other services, flags). If these values live inside the container image, every change forces a rebuild and a republish of the image. Changing a URL should not require a new build.
The concept
Problem 1: the Service. The Service is a stable entry point that finds the Pods by label and balances traffic among them. The flow is:
- A request arrives at the Service, which has a fixed IP and name.
- The Service selects the Pods by label selector (the mechanism from Stage 03).
- Traffic is distributed in a balanced way among the healthy replicas.
The Service name becomes an internal hostname of the cluster. If the Service is called auth-service, any Pod in the cluster can reach http://auth-service, even if the Pods behind it change IP repeatedly.
There are three types of Service:
- ClusterIP (the default): internal IP, reachable only from inside the cluster. It serves communication between services (for example, API to database).
- NodePort: opens a fixed port (from 30000 to 32767) on every node. Access from outside is done through
node-IP:port. It is the way to expose something on Minikube. - LoadBalancer: provisions an external load balancer with a public IP. It is the type used in production in the cloud (AWS, GCP, Azure).
Problem 2: the ConfigMap. The ConfigMap stores configuration in an object separate from the container. You inject it into the Pod in three ways:
- environment variables (the most common, via
envFrom); - mounted files (great for long configurations);
- command-line arguments.
When the configuration changes, you update the ConfigMap and the image stays the same, with no rebuild. But pay attention to one detail: environment variables are read when the container starts. Updating the ConfigMap does not change the variables of a Pod that is already running; the Pod needs to be recreated to see the new values (you will see this happen in practice in Stage 09). ConfigMaps mounted as files, on the other hand, are usually updated inside the Pod after some time, without recreating it, but the app needs to reread the file to use the new value.
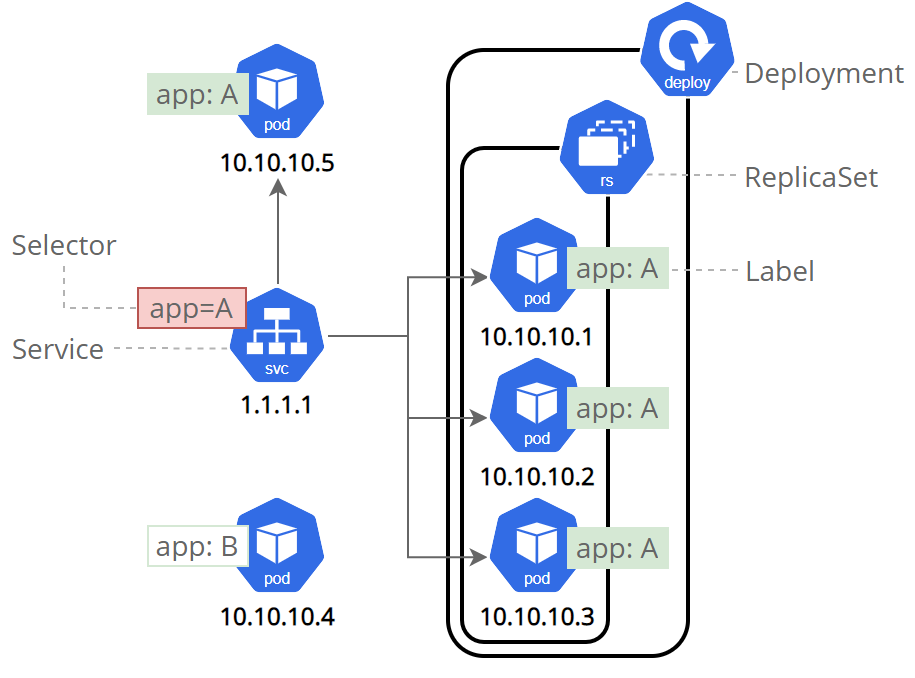
app=A, not by IP. The Pod with app: B gets no traffic from this Service. Deployment and ReplicaSet are covered in Stage 05.Diagram: kubernetes.io, The Kubernetes Authors, CC BY 4.0Key concepts
Service
stable address (IP and name) that selects Pods by label and balances traffic.
selector
the key-value pair that links the Service to the Pods; it must match the label of the Pods.
port / targetPort / nodePort
port is where the Service listens; targetPort is the container port that receives; nodePort is the port exposed on the node (only for the NodePort type).
ClusterIP
internal access only. NodePort: external access through a node port. LoadBalancer: external access through a public IP in the cloud.
Endpoints
the list of Pod IPs the Service is actually using; empty when no Pod matches the selector.
ConfigMap
object with key-value configuration pairs, separate from the image.
envFrom
injects all the keys of a ConfigMap as environment variables (read only when the container is created).
Secret
sibling of the ConfigMap, meant for passwords and keys.
Look at the selector
Create the etapa04/ folder and save this stage's manifests in it.
# app.yaml: save the Service in this fileapiVersion: v1kind: Servicemetadata:name: meu-service # becomes the internal hostnamespec:type: NodePort # switch to ClusterIP (internal) or LoadBalancer (cloud)selector: # ← THE LINK: looks for Pods with this labelapp: myappports:- protocol: TCPport: 80 # port the Service listens ontargetPort: 80 # container port that receivesnodePort: 30080 # port exposed on the node (NodePort only)
The Service selector matches the Pod label (app: myapp), exactly the meu-pod from Stage 03. This is how the Service knows where to send traffic.
Essential commands for this stage
Hands-on
- With the
meu-podfrom Stage 03 running (labelapp: myapp), save the Service YAML asetapa04/app.yamland apply it. - Run
minikube service meu-service --urland open the URL in the browser. Observe the nginx welcome page. You reached an ephemeral Pod through a stable address. - Test the link: delete the pod (
kubectl delete pod meu-pod) and reload the browser. Observe that the page stops loading (the browser shows connection refused or timed out, depending on the system and the driver), since there is no Pod left with the label. Confirm the cause withkubectl get endpoints meu-service: the endpoints list is empty.Recreate the pod with$ kubectl get endpoints meu-serviceNAME ENDPOINTS AGEmeu-service <none> 5mkubectl apply -f ../etapa03/meu-pod.yamland reload. Access is back without you touching the Service, andkubectl get endpoints meu-serviceshows an IP again (something like10.244.0.7:80). - Apply the ConfigMap and the pod (
kubectl apply -f configmap-pod.yaml) and runkubectl exec pod-config -- env. ObserveMENSAGEMandMODOin the list of variables. - Clean up the objects of this stage and the previous one:(The order of the lines may vary.) Also close the$ kubectl delete -f app.yaml -f configmap-pod.yaml -f ../etapa03/meu-pod.yamlservice "meu-service" deletedconfigmap "minha-config" deletedpod "pod-config" deletedpod "meu-pod" deleted
minikube serviceterminal, with Ctrl+C.
Tip: Golden rule: expose the minimum. A database should be ClusterIP, invisible from outside. Only the system's entry point becomes NodePort or LoadBalancer. For passwords and keys, the safe sibling of the ConfigMap is the Secret.
Takeaway: A Service gives a fixed address to Pods that change (finding them by label); a ConfigMap takes configuration out of the image, but environment variables only change when the Pod is recreated.
Stage 05 self-healing + scale
Self-healing and scaling with ReplicaSets and Deployments
The problem
So far you have created Pods manually, which is fine for learning. In production, three situations break this model.
The concept
Two pieces solve this, one wrapping the other.
ReplicaSet: guarantees the number of replicas. You declare replicas: 3 and it monitors the Pods by label selector. If a Pod disappears, the ReplicaSet notices that the count dropped and creates another in seconds, without anyone asking. This is self-healing, the desired state from Stage 01 maintained in practice. The ReplicaSet takes care of Pods that disappear. If what fails is only the process inside the container (a crash), the Pod still exists and whoever restarts the container is the kubelet, inside the same Pod; this separation is detailed in Stage 07.
Deployment: manages versions. It creates and manages the ReplicaSet under the hood and adds:
- Rolling Update: when you change the image, the Deployment brings up new replicas and shuts down the old ones gradually, and the service never goes down.
- Rollback: if the new version breaks,
kubectl rollout undoreturns to the previous one in seconds. - Manual scaling:
kubectl scale --replicas=5changes the number of replicas with one command.
Each version of the template has its own ReplicaSet. When the version changes, the Deployment creates a new ReplicaSet and shrinks the old one to zero. The name of a Pod reveals who it belongs to: in nginx-fiap-7d4b9c-aaa, the 7d4b9c part identifies the ReplicaSet (the version), and the final suffix identifies the Pod. When the middle suffix changes in the middle of a rolling update, you are looking at Pods from a new ReplicaSet.
The ReplicaSet and Deployment YAMLs are almost identical, but day to day we nearly always use the Deployment, precisely because of version control.
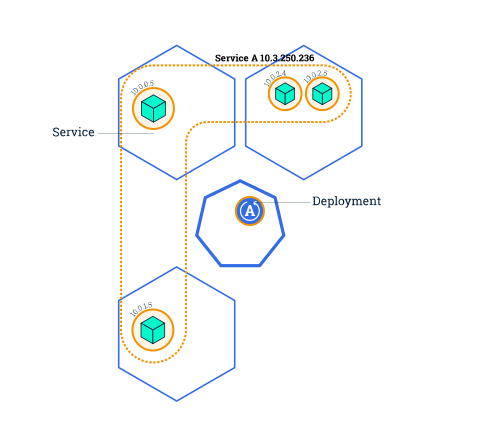
1. Before the update: every Pod runs the old version behind the Service.
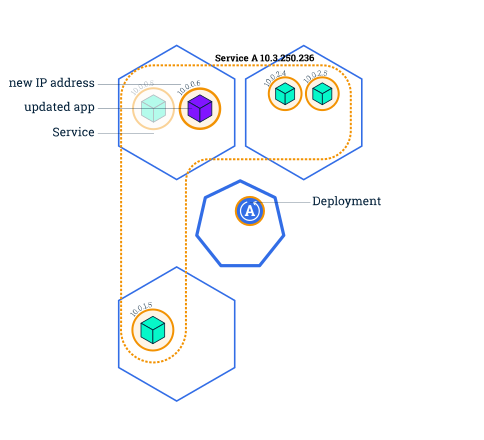
2. A new Pod comes up with another IP; an old one starts to leave.
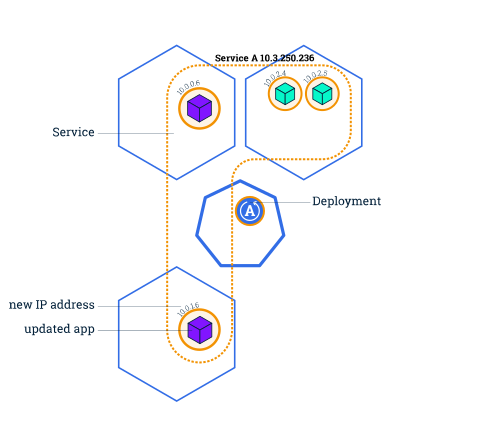
3. The swap continues one Pod at a time, and the Service keeps serving with the ready Pods.
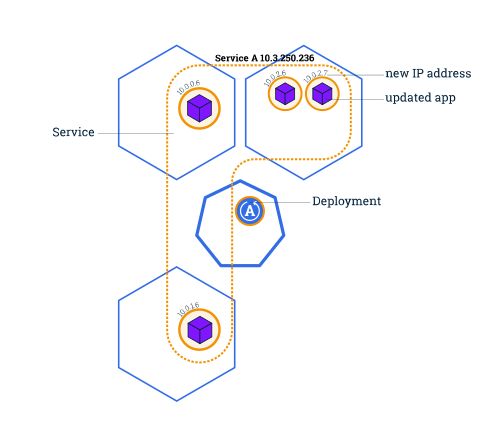
4. Done: every Pod is on the new version, and the Service address did not change.
Key concepts
ReplicaSet
keeps N replicas running at all times; if one goes down, another is born. It selects Pods by label selector.
Deployment
manages ReplicaSets and the version history; it is the object you use in practice.
template
the Pod mold embedded in the Deployment (it is the Pod skeleton from Stage 03).
Rolling Update
gradual version swap, with no downtime.
Rollback
return to a previous revision with rollout undo.
Revision
each change to the Deployment template generates a revision in the history, and each revision corresponds to a ReplicaSet.
The complete Deployment and its life cycle
Create the etapa05/ folder and save the manifest below in it as deployment.yaml.
apiVersion: apps/v1kind: Deploymentmetadata:name: nginx-fiapspec:replicas: 3 # I want 3 copies, alwaysselector:matchLabels:app: nginx-app # I manage the Pods with this label...template: # ...and this is the "mold" of each Podmetadata:labels:app: nginx-app # must match the selector ↑spec:containers:- name: nginximage: nginx:1.14.2 # changing this version triggers the rolling updateports:- containerPort: 80
The template is literally the Pod skeleton from Stage 03 inside the Deployment. Nothing here is new: the Deployment composes pieces you already know.
Essential commands for this stage
Hands-on
This is the central exercise of the guide. Take it calmly and observe each state.
- Apply
deployment.yamland confirm the 3 podsRunning. Also runkubectl get rsand observe thenginx-fiap-<hash>ReplicaSet with 3 replicas: the prefix of the Pod names is its name. - Delete a pod by hand (copy a real name from
kubectl get pods) and runkubectl get podsagain, quickly. Observe the replacement inContainerCreating. You tried to violate the desired state and the cluster corrected it. - Run the rolling update to
nginx:1.16.1and follow it withkubectl rollout status. Observe the success message. Runkubectl get rsand observe that there are now two ReplicaSets: the new one with 3 replicas and the old one with 0. This is why the suffix of the Pod names changed. - Break it on purpose with the image
nginx:nao-existe. Observe inkubectl get podsthe old podsRunningholding the service and the new ones inImagePullBackOff, and inkubectl get rsa third ReplicaSet withREADY 0. - Run
kubectl rollout undo deployment/nginx-fiapand confirm withkubectl rollout history deployment/nginx-fiap. Observe that the list goes 1, 3, 4: revision 2 became 4. Confirm the current image withkubectl describe deployment nginx-fiap | grep Image, which should shownginx:1.16.1. You did a rollback in one command. - Clean up:
kubectl delete -f deployment.yaml(output:deployment.apps "nginx-fiap" deleted). The Deployment's ReplicaSets and Pods are removed along with it.
Tip: Do the self-healing test at least once: apply the deployment, delete a pod by hand and watch the replacement be born. That is the moment when the "desired state" model stops being theory.
Takeaway: Nobody creates a standalone Pod in production: the Deployment guarantees N replicas (self-healing), swaps versions without downtime and goes back in one command, using one ReplicaSet per version.
Stage 06 data persistence
Volumes, data that outlives the Pod
The problem
Pods are ephemeral, and Stage 05 showed how frequent that is: pods are recreated at every rolling update. For a stateless API this is great. For a database it is a disaster. Imagine the e-commerce PostgreSQL Pod being recreated during an update, and all the Black Friday orders disappearing with it, because they were written to the container's filesystem. Real data cannot live inside the container.
The concept
Kubernetes solves this with a chain of four concepts: Volume, PersistentVolume (PV), PersistentVolumeClaim (PVC) and StorageClass (SC).
- The PVC is the storage *request*: "I want 1Gi, read and write by one node".
- The PV is the *real disk* that fulfills the request (NFS, AWS EBS, hostPath and others).
- The StorageClass describes *types* of disk (standard, fast SSD) and lets the cluster create PVs automatically when a PVC asks for them.
The Pod references only the PVC and does not need to know where the disk physically is. This separation lets the same Pod YAML run on Minikube and on AWS, changing only what fulfills the request. On Minikube, the standard StorageClass already provisions PVs automatically: you create the PVC and the PV appears.
The most common volume types:
- emptyDir: born empty together with the Pod and dies with the Pod. It serves for temporary files and for sharing data between containers of the same Pod.
- hostPath: mounts a directory of the node inside the container. It is useful in development and dangerous in production, because it ties the Pod to that node.
- persistentVolumeClaim: the right way for real data, which survives restarts and recreation of the Pod.
The PVC access modes define who can mount the volume:
- ReadWriteOnce (RWO): read and write by a single node. It is the typical case for a database.
- ReadOnlyMany (ROX): read-only, by several nodes. It serves static assets.
- ReadWriteMany (RWX): read and write by several nodes. It requires NFS or an equivalent backend.
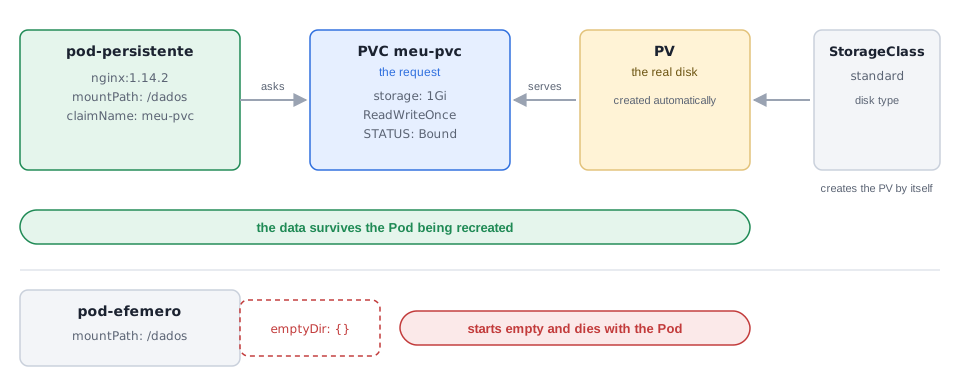
standard StorageClass. With emptyDir, the data lives only as long as the Pod exists.Diagram: made for this guideKey concepts
emptyDir
temporary volume that lives and dies with the Pod.
hostPath
node directory mounted in the container; ties the Pod to the node.
PVC (PersistentVolumeClaim)
storage request made by the user.
PV (PersistentVolume)
the disk that fulfills the request.
StorageClass
storage profile that provisions PVs automatically.
Bound
status indicating that the PVC was bound to a PV.
volumeMounts / volumes
in the Pod, volumes declares the source and volumeMounts defines where it appears inside the container.
Write, destroy, read back
Create the etapa06/ folder and save this stage's manifests in it.
# pvc.yamlapiVersion: v1kind: PersistentVolumeClaimmetadata:name: meu-pvcspec:accessModes:- ReadWriteOnce # one node reads and writes (typical for a database)resources:requests:storage: 1Gi # how much disk I want# on Minikube, the "standard" StorageClass provisions the PV by itself
Essential commands for this stage
Bound indicates success)standard StorageClass, the corresponding PV is usually deleted along with it, data included (the default reclaim policy is Delete; check your cluster's with kubectl get storageclass)Hands-on
- Apply the PVC and run
kubectl get pvc. Observe theSTATUS Bound: the request was fulfilled by an automatically created PV. Confirm withkubectl get pv. - Run the complete sequence from the example: write the file, delete the pod, recreate the pod, read the file. Observe the
sobrevivi!come back. This is the PVC contract. - Contrast experiment: save
pod-emptydir.yamland repeat the sequence (write, delete, recreate, read). Observe theNo such file or directoryat the end: the file vanished. This is the difference between ephemeral and persistent, seen in practice. - Clean up, in this order:
kubectl delete pod pod-persistente pod-efemeroand thenkubectl delete pvc meu-pvc. With the PVC deleted,kubectl get pvshould be empty (the PV was removed along with it, as described above).
Tip: Important data always sits behind a PVC. If data vanished after a restart or a recreation, it was almost certainly in emptyDir or in the container's own filesystem.
Takeaway: The PVC is the request, the PV is the disk, the StorageClass describes the disk types, and data that matters always lives behind a PVC.
Stage 07 app health
Probes, how the cluster knows your app is alive
The problem
At 3 a.m., your app enters a deadlock. The process is still up, so as far as Kubernetes is concerned everything is Running, but no request is answered. The recovery mechanisms you have seen so far act when a process ends or when a Pod disappears; none of them sees a process that is alive but stuck. There is also a similar case: the app has just started, but it is still loading data and should not receive traffic, and the Service is already sending requests to it. Without extra information, the cluster cannot tell "running" from "working".
The concept
Before probes, it is worth separating three situations that in everyday talk everyone calls "the app went down", because each one is handled by a different mechanism:
- The process inside the container ends (a crash, out of memory, an unhandled exception). The Pod still exists and the one that reacts is the node's kubelet: it restarts the container inside the same Pod, according to the Pod's
restartPolicy(the default isAlways). The Pod's name and IP do not change, and theRESTARTScolumn goes up. This happens with no probe configured. - The Pod disappears (someone deleted it, the node went down). The whole Pod ceases to exist and the one that reacts is the ReplicaSet (Stage 05), which creates a new Pod, with a new name and IP. A standalone Pod, without a ReplicaSet or Deployment, does not come back.
- The process is still alive but stuck (deadlock, infinite loop, exhausted dependency). Nothing ended and no Pod disappeared, so the two previous mechanisms do not notice. Only a liveness probe detects it, and when it fails the kubelet restarts the container, as in case 1.
Probes are health checks declared in the Pod manifest. The kubelet runs them periodically and acts according to the result.
There are three probes, and the most important point is what happens when each one fails:
- Liveness asks "is it alive?". If it fails, the kubelet restarts the container (inside the same Pod). It is for apps that hang and only come back with a restart.
- Readiness asks "is it ready to receive requests?". If it fails, the Pod leaves the load balancer (the Service stops sending traffic) without being restarted. It is for apps that load data before serving or that are temporarily unavailable.
- Startup asks "has it finished initializing?". While it runs, it holds back the other probes, preventing liveness from killing a slow app too early.
Each probe can check in three ways:
- httpGet: the kubelet makes a GET to an endpoint (for example
/health) and expects a success status (200 OK). It is the most common. An error status, such as 404 or 500, counts as a failure. - tcpSocket: tests whether the port accepts a connection. It serves services that do not speak HTTP.
- exec: runs a command inside the container; exit code 0 means healthy.
Good practices from the lesson: use all three probes together in production; use different endpoints for each probe; start with the default settings and adjust intervals only when the app asks for it; monitor probe failures (for example, with Prometheus), because they are the first sign of trouble.
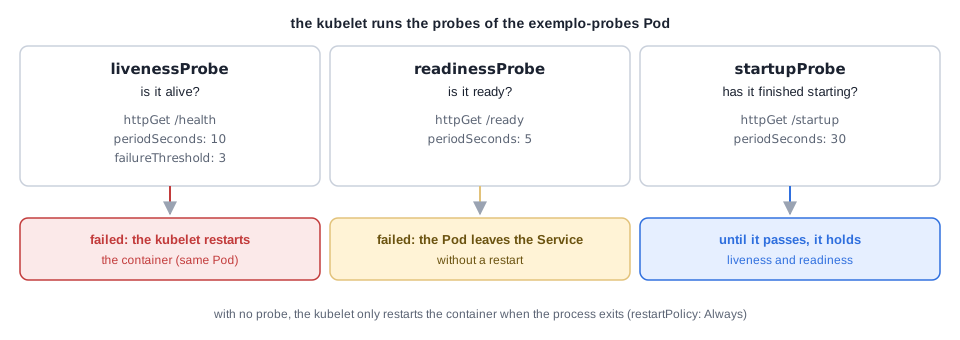
Key concepts
restartPolicy
Pod policy for containers that end (default Always); it is what restarts a container that went down, with or without probes.
Liveness probe
failed, the kubelet restarts the container.
Readiness probe
failed, the Pod leaves the load balancer without restarting.
Startup probe
until it passes, the others stay suspended.
httpGet / tcpSocket / exec
the three checking mechanisms.
periodSeconds
how many seconds apart the probe runs.
failureThreshold
how many consecutive failures are tolerated before acting (the default is 3).
initialDelaySeconds
how long to wait before the first check.
Worked examples
apiVersion: v1kind: Podmetadata:name: exemplo-probesspec:containers:- name: appimage: exemplo:latestports:- containerPort: 80livenessProbe: # failed → RESTARTS the containerhttpGet:path: /healthport: 80periodSeconds: 10 # checks every 10stimeoutSeconds: 5failureThreshold: 3 # 3 consecutive failures → restarts (3 is the default)readinessProbe: # failed → LEAVES the load balancerhttpGet:path: /ready # good practice: separate endpointport: 80periodSeconds: 5startupProbe: # holds the others until the app is uphttpGet:path: /startupport: 80initialDelaySeconds: 120 # slow app: waits 2minperiodSeconds: 30
This YAML is illustrative: the exemplo:latest image is fictitious. The runnable experiment comes next, and in Stage 09 you will see the probes working on a real image. A caveat about the startupProbe in the example: initialDelaySeconds: 120 is valid, but the most common way to give a slow app time is to multiply failureThreshold by periodSeconds (for example, 30 attempts every 10 seconds give up to 300 seconds). That way the startupProbe finishes as soon as the app responds, instead of always waiting a fixed delay.
Essential commands for this stage
Last State shows why the previous container endedHands-on
- Apply
liveness-exec.yamland runkubectl get pods -w. Observe theRESTARTScolumn go up by itself: the first restart appears about 45 seconds after the start (30s healthy plus 3 failures spaced 5s apart). Each increment is the kubelet restarting a container that stopped passing the check. - In another terminal, run
kubectl describe pod liveness-exec. Observe in the Events the pairWarning Unhealthyfollowed byNormal Killing. Learn to recognize this pair: in production, it is the diagnosis of a failing probe. - Run the crash experiment (
kubectl run crash ...) and compare. Observe thatRESTARTSalso goes up, butdescribeshowsLast State: TerminatedwithExit Code: 1and noLiveness probe failedevent. This is case 1, handled by the kubelet without a probe; the one in step 2 is case 3, which only liveness solves. - Clean up:
kubectl delete pod liveness-exec crash.
Tip: Running does not mean healthy. An app can be running and stuck in a deadlock. This is exactly why probes exist.
Takeaway: A process that crashes is restarted by the kubelet, a Pod that disappears is recreated by the ReplicaSet, and a process that is alive but stuck is detected only by liveness: a failed liveness probe restarts the container, a failed readiness probe takes the Pod out of the load balancer without restarting, and a startup probe holds back both until the app finishes starting.
Stage 08 automatic scaling
HPA, automatic scaling based on metrics
The problem
Go back to the e-commerce site from Stage 01: Black Friday has arrived. You already know how to scale manually with kubectl scale --replicas=... (Stage 05). Staying on call at the terminal adjusting replicas at every traffic peak, including at 2 a.m., is not viable. The cluster should measure the load and adjust the number of replicas by itself.
The concept
The Horizontal Pod Autoscaler (HPA) monitors Pod metrics (CPU, memory and others) and adjusts the number of replicas between a minimum and a maximum that you define.
How it works: the HPA compares the current utilization of the Pods with the configured target (for example, keeping average CPU at 70%). If utilization goes above the target, it creates replicas, up to the maximum. If it drops, it removes replicas, down to the minimum, saving resources. The scale down is deliberately slow (about 5 minutes of stability) to avoid constant oscillation in the face of quick load variations.
Once an HPA controls a Deployment, it is the HPA that decides the number of replicas within the range minReplicas to maxReplicas. The replicas value written in the Deployment manifest holds only until the HPA acts: if it is above the floor and there is no load, the HPA reduces it after a few minutes (you will see this in Stage 09).
Which metrics the HPA can use. CPU and memory are read natively, through the metrics-server. The others require additional components installed in the cluster: custom metrics from your app (requests per second, queue size), external metrics (for example, coming from Prometheus) and disk I/O need a custom or external metrics adapter. Without that adapter, only CPU and memory are available. The right metric depends on the app's profile: a CPU-heavy app scales by CPU; one that consumes a lot of RAM scales by memory.
Two prerequisites are often forgotten:
- The cluster needs the metrics-server to read CPU and memory. On Minikube:
minikube addons enable metrics-server. - The container must declare `resources.requests.cpu`, because "70% CPU" means 70% of what the Pod requested. Without requests, the HPA shows
<unknown>and does not scale.
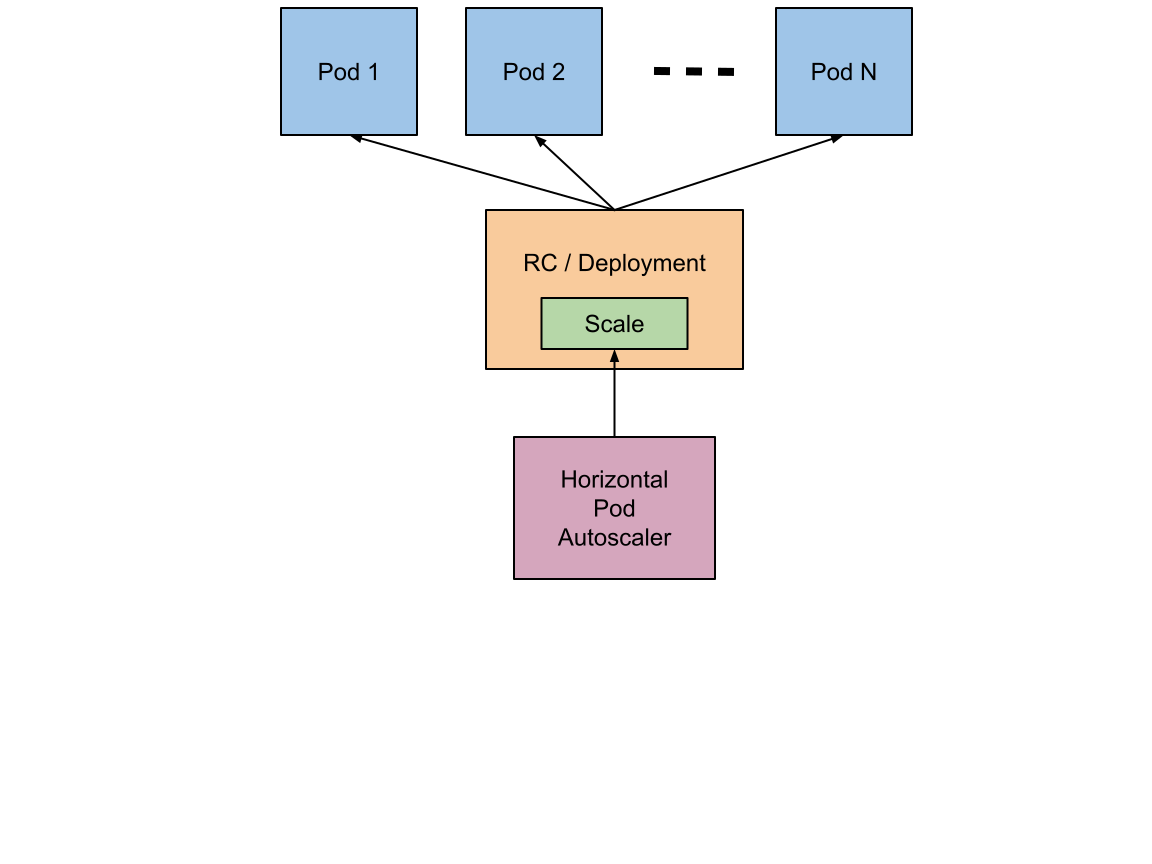
Key concepts
HPA
controller that adjusts the number of replicas of a Deployment according to metrics.
metrics-server
component that collects CPU and memory from the Pods; prerequisite of the HPA.
resources.requests
amount of resource the container declares it needs; basis of the percentage calculation.
resources.limits
ceiling of resource the container may consume.
millicore (m)
CPU unit; 100m equals 0.1 CPU.
minReplicas / maxReplicas
floor and ceiling of replicas; the HPA works within that range.
averageUtilization
average usage percentage, relative to requests, that the HPA tries to maintain.
Metrics adapter
extra component needed for metrics other than CPU or memory.
Deployment, HPA, Service and load test
Create the etapa08/ folder and save the three manifests in it (the names deployment.yaml and service.yaml also appear in Stage 09, hence the separation by folder).
# deployment.yamlapiVersion: apps/v1kind: Deploymentmetadata:name: nginx-hpaspec:replicas: 1 # starts with 1; the HPA takes over from hereselector:matchLabels:app: nginx-hpatemplate:metadata:labels:app: nginx-hpaspec:containers:- name: nginximage: nginx:1.14.2resources: # WITHOUT requests the HPA does not calculate %requests:cpu: "100m" # 100 millicores = 0.1 CPUlimits:cpu: "200m"
Essential commands for this stage
Hands-on
The final experiment of this part, which joins Deployment, Service and HPA.
- Enable the metrics-server and apply the three YAMLs (Deployment, HPA, Service). Run
kubectl get hpaand observe the targets. If<unknown>appears, wait about 1 minute: the metrics-server needs to collect the first reading. - Start the load generator in one terminal and run
kubectl get hpa -win another. Observe the CPU percentage go above 70% and then theREPLICAScolumn go up. If the percentage stalls below the target, use plan B. Confirm withkubectl get pods: new pods were born without any command from you. - Stop the load (Ctrl+C) and keep watching. Observe that the replicas take about 5 minutes to shrink. This slowness is deliberate.
- Run
kubectl top podsduring the test to see the raw metric that feeds the HPA. - Clean up:
kubectl delete -f deployment.yaml -f hpa.yaml -f service.yaml. Thegeradorpod was created with--rmand deleted itself when you interrupted the load; confirm withkubectl get pods. Keep the metrics-server enabled, because Stage 09 also uses the HPA.
Tip: If kubectl get hpa shows <unknown> in the targets, there are two possible causes: the metrics-server is not active or the container did not declare resources.requests.
Takeaway: The HPA is the desired state applied to scaling: you define a target, a floor and a ceiling, but without the metrics-server and without resources.requests it sees nothing, and only CPU and memory come ready (the rest requires an adapter).
Stage 09 bonus · real docker hub image
Bonus, a professional application with a real Docker Hub image
The problem
The eight previous stages used nginx on purpose: a simple image, with no noise, so you could learn the mechanics of each piece. But a real deployment is not made of isolated pieces. Three questions only appear when you put everything together: how the pieces fit together in a real app, how to test probes in an application with real health endpoints (instead of the illustrative YAML from Stage 07) and which pieces to use, or leave out, for that specific app.
The concept
This stage builds a complete deployment with the stefanprodan/podinfo image from Docker Hub (docker.io/stefanprodan/podinfo). Podinfo is an open source project designed to be used in demonstrations. It exposes real /healthz and /readyz, accepts configuration through environment variables (PODINFO_UI_MESSAGE, PODINFO_UI_COLOR) and has a /panic endpoint that ends the process on purpose.
That last point deserves care, because /panic and liveness test different things. When the podinfo process ends, the one that restarts the container is the kubelet, through the Pod's `restartPolicy` (case 1 of Stage 07). This would happen even if the manifest had no livenessProbe at all. Liveness only comes into play in case 3, a process that is alive but does not respond in a healthy way. That is why this exercise uses /panic to demonstrate the restart of a container that went down, and tests liveness for real by pointing the probe at a path that does not exist, so that the endpoint starts returning 404 and the probe fails.
The four manifests fit together through the label app: podinfo, the same mechanism that stitched the whole guide together (Stage 03):
- The ConfigMap injects the variables via
envFrom(Stage 04). - The Deployment declares 3 replicas (Stage 05),
resources.requests(required for the HPA, Stage 08) and two probes: liveness on/healthzand readiness on/readyz(Stage 07). - The Service is NodePort because here podinfo is the system's entry point, applying the golden rule of Stage 04.
- The HPA reads the CPU declared in the Deployment and scales between 2 and 8 replicas (Stage 08).
There is an interaction between the Deployment and the HPA that is worth knowing: the Deployment declares replicas: 3, but the HPA has minReplicas: 2. While there is some load, or in the first minutes, you will see 3 replicas. Without load, after about 5 minutes (the stability window from Stage 08), the HPA reduces the Deployment to 2. From then on, the one in charge of the number of replicas is the HPA, and the manifest's replicas: 3 stops applying. In production, it is common to omit replicas from the Deployment when an HPA exists, precisely to avoid this dispute.
What was not included also matters. Not every piece you learned fits every app.
- The startupProbe (Stage 07) was left out because podinfo starts in fractions of a second. Using a piece just because it exists in the manual adds configuration with no benefit.
- The PVC (Stage 06) was also left out of the Deployment, for a technical reason. The problem: the PVC from Stage 06 uses
ReadWriteOnce, and that mode cannot be shared among replicas on different nodes. On Minikube (a single node), attachingvolumes.persistentVolumeClaimto a Deployment with several replicas may even start without complaint, but on a cluster with several nodes the extra replicas get stuck, competing for the same disk (the event shows up asFailedAttachVolume). The ways out, if the app needed state: a truly shared cache (podinfo has the--cache-serverflag to talk to a Redis) or one disk per replica, with a StatefulSet andvolumeClaimTemplates, a subject for the advanced module. Stage 06 remains valid: it is the right answer for its scenario, a single Pod with data, like a database.
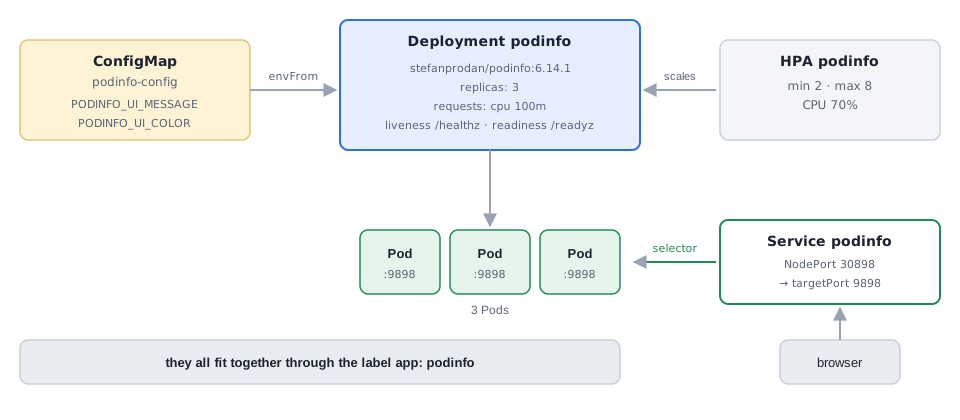
app: podinfo label, and the HPA takes over the Deployment's replica count.Diagram: made for this guideKey concepts
ConfigMap with envFrom
external configuration injected as variables (Stage 04).
Deployment with 3 replicas
self-healing and readiness for a rolling update (Stage 05).
Real probes
liveness on /healthz, readiness on /readyz (Stage 07).
restartPolicy
what restarts a container whose process ended (/panic), unrelated to liveness.
NodePort Service
the app is the entry point, so it is exposed (Stage 04).
HPA between 2 and 8 replicas
scales by the CPU declared in requests and, without load, reduces the 3 initial replicas to 2 (Stage 08).
Fixed version tag
using podinfo:6.14.1 instead of latest, so that the deploy is reproducible.
rollout restart
command that recreates the Pods of a Deployment, needed for them to read a changed ConfigMap.
Endpoints
list of Pods that are actually receiving traffic from a Service; Pods with a failing readiness leave it.
The four manifests and the complete test
Create the etapa09/ folder and save the four manifests in it.
# configmap.yamlapiVersion: v1kind: ConfigMapmetadata:name: podinfo-configdata:PODINFO_UI_MESSAGE: "olá do pitstop.dev!" # appears on the app screenPODINFO_UI_COLOR: "#34d399" # banner color in the UI
It is the same mechanism as Stage 04 (envFrom), but here the keys are variables that podinfo really reads to build its own interface.
Essential commands for this stage
Hands-on
In this exercise you build the complete deployment, provoke controlled failures and confirm each behavior. The command blocks for each step are in the example above.
- Save the four YAMLs in
etapa09/(configmap.yaml,deployment.yaml,service.yaml,hpa.yaml) and apply them with a singlekubectl applypointing to the four files. - Run
kubectl get pods,hpauntil you see the podsRunning(3 at the start) and the HPA with a real CPU value (not<unknown>). If it gets stuck, confirm that the Stage 08 metrics-server is still active. Remember that, without load, the HPA will reduce the 3 replicas to 2 in about 5 minutes; this is expected, and the following steps work with either number. - Run
minikube service podinfo --url, keep that terminal open and, in another, run the loopfor i in 1 2 3 4 5; do curl -s <URL> | grep hostname; done. Observe more than one hostname in the output. If you prefer the browser, know that it usually reuses the connection and may always show the same hostname. - Reproduce the ConfigMap gotcha: edit the message in
configmap.yaml, apply it withkubectl apply -f configmap.yaml, confirm thatkubectl exec ... envstill shows the old value and only then runkubectl rollout restart deployment/podinfo. Confirm the change again. (You can also usekubectl edit configmap podinfo-config, which opens the system's default editor, usually vi; editing the file and reapplying is simpler and keeps the YAML versioned as the source of truth.) - Provoke a crash with
curl .../panicand followkubectl get pods -wuntil you seeRESTARTSgo up by itself, without you restarting anything. Observe withkubectl describethat the previous container isTerminatedwith a nonzero exit code and that there is no liveness event: the one that restarted it was the kubelet, through therestartPolicy. - Test liveness for real: change the probe path to
/nao-existewithkubectl patch, wait about 30 seconds and observeRESTARTSgo up (the status may alternate withCrashLoopBackOffbetween one restart and the next, which is expected) and, indescribe, the eventsLiveness probe failed: HTTP probe failed with statuscode: 404andKilling. Restore withkubectl apply -f deployment.yamland runkubectl rollout status deployment/podinfo, waiting for thesuccessfully rolled outmessage before step 7, so thathead -n 1does not pick an old Pod that is still terminating. Know that thisapplysetsreplicasback to 3; the HPA reduces it to 2 again if there is no load. - Turn off the readiness of one Pod with
curl -X POST .../readyz/disableand, after about 15 seconds, confirm withkubectl get pods(READY 0/1,RESTARTSunchanged) andkubectl get endpoints podinfothat this Pod left the list, without being restarted. With 2 replicas, 1 IP remains; with 3, 2 remain. - Finish by generating load as in Stage 08 (the same busybox generator against
http://podinfo:9898) and observe the HPA scale this Deployment by itself. - Clean up:
kubectl delete -f configmap.yaml -f deployment.yaml -f service.yaml -f hpa.yaml. Close theminikube serviceterminal with Ctrl+C. If you want to shut the lab down,minikube stop.
Tip: The ConfigMap gotcha is a common mistake: editing the ConfigMap restarts nothing by itself (unless something like a Reloader takes care of it). In production, the command after applying a new configuration is almost always kubectl rollout restart deployment/<name>.
Takeaway: A professional manifest is not the sum of everything you learned: it is the choice of what the app needs (ConfigMap, replicas, real probes, Service, HPA) and the conscious refusal of what it does not need (startupProbe on a fast app, PVC on a Deployment with several replicas); and a process crash is handled by the kubelet, while only a probe that fails proves liveness.
Stage 10 free labs
Practice for free on real clusters
These platforms give you a terminal with a real Kubernetes cluster right in the browser, with nothing to install. Start with the 100% free ones and move to the paid ones only when you want bigger challenges.
Killercoda
100% freeInteractive Kubernetes scenarios right in the browser: you get a terminal with a real cluster and a guided script. Katacoda's successor.
Good for: Practice every stage of this guide without installing anything. Start here.
killercoda.com/kubernetesPlay with Kubernetes
100% freeA real, temporary Kubernetes cluster (4-hour sessions) in the browser, run by Docker. You build the cluster by hand with kubeadm.
Good for: Freely test kubectl commands and understand how a cluster comes together.
labs.play-with-k8s.comKube by Example
100% freeShort tutorials and examples maintained by Red Hat: one concept per page (Pods, Services, Deployments...), straight to the point.
Good for: Quickly review a specific concept, like a second explanation.
kubebyexample.comIntroduction to Kubernetes (LFS158)
100% freeThe Linux Foundation's official free course (who maintains K8s), also available on edX. Solid theory with a certificate of completion.
Good for: Consolidate the theory with the official material after finishing this guide.
training.linuxfoundation.orgKubernetes the Hard Way
100% freeKelsey Hightower's legendary walkthrough: building a cluster piece by piece, by hand, with no installers. It's "build the car bolt by bolt": once you've done it, you never look at the garage the same way.
Good for: Advanced level, for when you want to understand what Minikube hides from you.
github.com/kelseyhightowerKodeKloud
Free tier + paidGuided, challenge-style labs: "this Pod won't come up, figure out why." Some labs are free; the full catalog (plus CKA/CKAD practice exams) is paid.
Good for: Realistic troubleshooting, the closest thing to a technical interview.
kodekloud.comiximiuz Labs
Free tier + paidContainer and Kubernetes playgrounds in the browser with hands-on challenges. Several playgrounds and challenges are unlocked on the free plan.
Good for: Deeper experiments: networking, images, container internals.
labs.iximiuz.comSuggested route: at every stage of this guide, open Killercoda and repeat the commands in the matching scenario (Pods, Deployments, Volumes). After the 9 stages, use KodeKloud for troubleshooting challenges.
Stage 11 · review
Self-assessment checklist
Stage 01: Motivation and setup
- I can explain the difference between a container and a VM and why the container is lighter.
- I started Minikube and saw the
Readynode inkubectl get nodes. - I know what "desired state" means and can give an example.
Stage 02: kubectl and the API
- I created an imperative pod with
kubectl runand saw it reachRunning. - I provoked an
ImagePullBackOffon purpose and found the cause in the Events ofdescribe. - I can recite the debugging flow: get, describe, logs.
- I can explain the path of a command: kubeconfig, API Server, response.
Stage 03: Cluster, Pods and labels
- I can state the role of master, worker, etcd, kubelet, kube-proxy and API Server.
- I wrote a Pod YAML from scratch following apiVersion + kind + metadata + spec.
- I filtered pods with
-land can explain when to use a label and when to use an annotation.
Stage 04: Services and ConfigMap
- I exposed a pod via NodePort and opened the page in the browser with
minikube service --url. - I deleted the pod, saw the Service left without endpoints (
kubectl get endpoints) and saw access return when I recreated the pod. - I can say which Service type to use for an internal database, a test on Minikube and production in the cloud.
- I injected a ConfigMap as environment variables, confirmed with
kubectl exec -- envand can explain why changing the ConfigMap does not change the variables of a running Pod.
Stage 05: ReplicaSets and Deployments
- I deleted a pod of a Deployment and saw the replacement be born by itself (self-healing).
- I did a rolling update, broke a deploy on purpose and went back with
rollout undo. - I used
kubectl get rsto see one ReplicaSet per version and can explain why the suffix of the Pod names changes on a version swap. - I can explain why the old pods hold the service when the new image fails.
Stage 06: Volumes
- I can explain the chain PVC (request), PV (disk), StorageClass (disk types).
- I wrote a file to a PVC, destroyed the pod, recreated it and read the file back.
- I repeated the test with
emptyDir(in a Pod with another name) and saw the file vanish. - I can say when to use emptyDir, hostPath and persistentVolumeClaim.
Stage 07: Probes
- I can say what happens when each probe fails (liveness, readiness, startup).
- I can tell the three cases apart: process crash (the kubelet restarts the container), Pod that disappears (the ReplicaSet creates a new Pod) and process alive but stuck (only liveness detects it).
- I ran the liveness-exec experiment and saw the RESTARTS column go up by itself, with the pair
UnhealthyandKillingin the Events. - I can explain why
Runningdoes not mean healthy.
Stage 08: HPA
- I can state the two prerequisites of the HPA (metrics-server and resources.requests).
- I can say which metrics come ready (CPU and memory) and which require an adapter.
- I generated load and saw the HPA increase the replicas without any command from me.
- I can explain why the scale down takes about 5 minutes.
Stage 09: Professional application
- I applied the four podinfo manifests and saw the replicas
Runningwith the HPA reading the CPU. - I reproduced the ConfigMap gotcha and solved it with
rollout restart. - I provoked a crash with
/panicand can explain that the restart was done by the kubelet (restartPolicy), not by liveness. - I provoked a real liveness failure (probe on a nonexistent path, 404) and saw the events
Liveness probe failedandKilling. - I restored the probe with
kubectl applyand waited forrollout statusto finish before moving on. - I took a Pod out of the Service with
/readyz/disableand confirmed withkubectl get endpointsandREADY 0/1, with no restart. - I can explain why the HPA reduces the 3 replicas to 2 and why the startupProbe and the PVC were left out of this Deployment.
Next steps: with all items checked, repeat the exercises on one of the platforms listed in the previous section, this time without consulting the guide. The next topic is the advanced module, where the StatefulSet mentioned in Stage 09 appears.
Teacher's notes: technical precisions
- This block gathers details that help you read the examples safely. Nothing here changes the path of the exercises; they are clarifications about behaviors that tend to raise questions.
- About what you will see in the terminal
- Example outputs. The outputs shown are typical formats. Pod names, ReplicaSet hashes, IPs, ages and columns vary with the Kubernetes version and the environment. Compare the structure, not the exact text. The
rollout historyandkubectl topoutputs are approximate, and theget pods -woutputs are shortened: in a real environment, the lines appear with longer intervals than the example suggests. - API path (Stage 02).
kubectl get podsin thedefaultnamespace makesGET /api/v1/namespaces/default/pods. The path/api/v1/podslists pods from all namespaces.-v=6shows the actual request, and the format of the log line varies between kubectl versions. - kubectl version before the cluster (Stage 01).
kubectl versionwithout--clienttries to query the server. Beforeminikube startthis ends in a connection error, which is expected and does not indicate a faulty installation. - `kubectl get endpoints` (Stages 04 and 09). In recent Kubernetes versions, the command may display a deprecation warning in favor of EndpointSlices. It remains useful for the exercises; the alternative is
kubectl get endpointslices. - About behaviors that surprise
- Rollback (Stage 05).
rollout undogoes back to the immediately previous revision, not to the original. In the example, it restoresnginx:1.16.1, notnginx:1.14.2. The restored revision gets a new number in the history and reuses its ReplicaSet. - `kubectl delete pvc` (Stage 06). With Minikube's
standardStorageClass, the reclaim policy is usuallyDelete: deleting the PVC deletes the PV and the data. Check your cluster's policy withkubectl get storageclass. In production environments, this policy is an important decision. - Changing an existing Pod (Stage 06). The
specof a Pod cannot be modified after it is created (with few exceptions, such as the image). To change the volume type, create a Pod with another name or delete and recreate the Pod. - Restart timing (Stage 07). In the liveness-exec experiment, the first restart happens at around 45 seconds (30s healthy plus 3 failures spaced 5s apart). The following cycles may take longer, because the kubelet waits for the container to terminate (up to 30s by default, the
terminationGracePeriodSeconds) before recreating it. - Who restarts what (Stages 07 and 09). The kubelet restarts containers whose process ended, because of the
restartPolicy, with or without a probe. The liveness probe exists for the case where the process is still alive but does not respond. An endpoint that brings the process down (like podinfo's/panic) demonstrates the first case, not the second. - HPA metrics (Stage 08). The HPA natively reads CPU and memory, via the metrics-server. Requests per second, Prometheus metrics, disk I/O and any other metric require a custom or external metrics adapter installed in the cluster.
- HPA and `replicas` (Stages 08 and 09). With an active HPA, the number of replicas is decided by it within
minReplicasandmaxReplicas. The Deployment'sreplicasworks as a starting point and is adjusted by the HPA, which explains the 3 replicas becoming 2 in Stage 09. Reapplying the manifest (kubectl apply) setsreplicasback to the value written in it, and the HPA adjusts again after the stability window. - Service balancing (Stage 09). Balancing is per connection and the choice of replica is random. Clients that reuse the connection (like a browser) tend to always talk to the same replica.
- startupProbe (Stage 07). The most common way to give a slow app time is
failureThresholdmultiplied byperiodSeconds, instead of a fixedinitialDelaySeconds. The example withinitialDelaySeconds: 120is valid and was kept out of fidelity to the source material. - Terminology and points to verify
- Master node and control plane. The lesson material uses "Master node". Current Kubernetes documentation prefers control plane, which is what appears in the ROLES column of
kubectl get nodesin Stage 01. Both names refer to the same thing. - Image tag (Stage 09). The tag
stefanprodan/podinfo:6.14.1comes from the guide's material. Confirm on Docker Hub that it exists before running; if it does not, use a more recent published tag. The fixed tag, instead oflatest, is the didactic point and remains. - Supporting manifests. The files
liveness-exec.yaml(Stage 07), the HPAservice.yaml(Stage 08) andpod-emptydir.yaml(Stage 06) are supporting additions to the exercises, following the pattern of the official Kubernetes documentation.