study guide · advanced Kubernetes in 9 stages + bonus
Advanced Kubernetes
through the F1 lens.
This guide continues the Kubernetes basics module and teaches you to operate a production cluster, in nine stages and a bonus. Before you start, you need to know what the basics module covered: Pods, Deployments, Services, ConfigMaps, probes, the HPA and kubectl with declarative YAML, all practiced on Minikube. You begin with the health and resources of each application and with control over which nodes the Pods run on; then you study update strategies, packaging with Helm, Blue/Green and canary deployments, node autoscaling with Karpenter and application autoscaling with KEDA, and security with identity, RBAC and automatic certificates. In the bonus stage, you take the podinfo app from the basics module to a production format, combining Helm, a minimal ServiceAccount, topology spread, a PodDisruptionBudget, a tuned rollout and a canary. Before the stages, the next section introduces the F1 lens of the guide: a general comparison that shows the same operation working inside a Formula 1 team.
Each stage depends only on what was explained before it and ends with a small exercise that proves you understood. Operating a cluster is learned by causing failures on purpose and watching the reaction, so do not skip the "Hands-on" blocks.
How to use this guide: keep a terminal open next to the text. The commands were designed for Minikube (installed in the basics guide) and, from Stage 04 on, for Helm. When an example shows the expected output, compare it with yours: Pod names, IPs, versions and timings will vary, and the structure of the output is what matters. Shortened outputs are marked with (...), and outputs that depend on a version or on the environment are shown as approximate. Organize the files in one folder per stage (etapa01/, etapa02/ and so on), because names such as deployment.yaml repeat, and run the cleanup step at the end of each stage before moving on.
What runs on Minikube and what is read-only: Stages 01, 02 (with a 2-node cluster), 03, 04, 05 and 06 run entirely on Minikube. In Stage 07 (Karpenter), Karpenter itself requires AWS and is read-only; what you run locally is the cause that triggers it, a Pending Pod caused by a lack of capacity. In Stage 08, KEDA runs on Minikube (with a Redis queue trigger), and the RabbitMQ example is read-only. In Stage 09, RBAC and cert-manager run locally, and IRSA and Workload Identity are read-only because they depend on a cloud account. Istio and Argo Rollouts (Stage 06) are also read-only, and the canary is practiced with the native technique based on the replica ratio. Stage 10 runs on Minikube from end to end.
The F1 lens of this guide
The fine-grained operation of an F1 team
The basics guide presented the cluster as a Formula 1 team on a Grand Prix weekend. On the pit wall (the gantry facing the track) sit the engineers who decide; in the garages are the mechanics who execute; the cars on the track do the work; and each car is assembled from a specification sheet, the list of parts and versions that defines the car. The regulations limit each team to two cars per race, car 1 and car 2. This guide looks at the same team at a finer level.
The health of each car reaches the pit wall through telemetry, the sensors that continuously transmit the state of every system, and the race engineer (the person who follows one car and talks to the driver over the radio) asks three different questions of that data. The first is whether a system has frozen: in that case, the engineer asks the driver for a reset, which restarts only that system, without swapping the car. The second is whether the car is fit to go on track right now: a car with a problem under repair stays in the garage, without being taken apart, and returns when it is ready. The third applies only at the start of the day: the power unit (the car's engine, which combines the combustion engine and the electrical part) is warmed with hot fluids before it is started, and nobody judges the performance of an engine that is still warming up.
Resources work with a floor and a ceiling, and both numbers describe the same quantity. Take electrical energy. The floor is the share reserved for each car: each garage receives a fixed amount of energy from the circuit, the team reserves a slice of it for each car's work and only places a car in a garage where its slice still fits. The ceiling is the maximum energy the car may spend. On track, the regulations impose this ceiling on the electrical energy the power unit releases per lap: when the car reaches it, the electrical part stops pushing, the car loses speed at the end of the straight and keeps moving. This effect is called clipping. The floor guarantees that the combined energy is available; the ceiling prevents a car from spending more than allowed.
When space, energy or people run short in the garage, there is an order of priority. The work that secures the car for the next session (each period of track time in the weekend: practice, qualifying and the race) stays. Among the rest, the work that has reserved everything it uses is the last to be cut, and the optional work, with nothing reserved, is postponed first.
Not every garage suits every job. An area with special equipment has a sign on the door that bars anyone without authorization; having the authorization allows entry but does not oblige anyone to go there, and whoever needs that equipment asks for the area by name. The team distributes the cars among the garages in balanced numbers, so that a problem in one garage (a power failure, a fire) does not leave the team with no car at all. When a garage needs maintenance, the team stops sending work there and removes in an orderly way what was in it, under a fixed rule: never leave the team with fewer ready cars than the agreed minimum. New parts arrive throughout the season as upgrades, each with its version recorded on the specification sheet. The team can fit the upgrade to one car at a time, always keeping one car ready; it can change the version of both cars at once when the change touches something both share (new control software that records telemetry in a format the pit wall data system, the same for both cars, cannot read alongside the old format), accepting a period with no car ready; and it can go back to the previous version, which remains on record. There are two more cautious ways to debut a version. One is to assemble a second complete chassis with the new specification, leave it ready next to the current one and hand over to it the race number (the number by which the car is called on the radio and in the timing), with the old chassis left intact so the team can go back to it if needed. The other is to fit the new part only on car 1, keep car 2 with the old part and compare the telemetry of both under the same conditions before taking the upgrade to both cars.
The setup (the set of adjustments for wing, suspension and ride height) is not rewritten for every event. The team keeps a base setup with fields to fill in and an adjustment sheet per type of circuit: less wing for a circuit with long straights, more wing for a circuit with slow corners. The car prepared for a weekend is the base setup filled in with the sheet of that circuit, and each change receives a revision number. The facilities and the people also follow the volume of work. Logistics sizes the garage facilities that go to each event to the size the expected work requires, and stops bringing what would sit idle. The support crew that produces parts at the factory is called in according to the list of orders arriving from the track: the more orders, the more people working, and with no orders nobody is on standby. Finally, access is controlled by credentials. Each person has a pass that says who they are and where they may enter: the paddock (the work area behind the garages, closed to the public), the garage, the pit lane (the lane in front of the garages, where cars enter to stop). Each role receives only the access it needs, and the pass is issued by whoever organizes the event, with a defined validity. To enter an area controlled by another organization, the person exchanges the team pass for a temporary, short-lived pass issued by that organization. When passes are replaced, there is a period in which the old and the new are valid together.
It is the same operation that Kubernetes performs at the fine level. The race engineer's three questions are the probes: the reset of a system is the liveness, which restarts the container; the car that waits in the garage until it is ready is the readiness, which takes the Pod out of the Service without restarting it; the warm-up of the power unit is the startup. The slice of energy reserved in the garage (the floor) is the request, the energy ceiling with clipping is the CPU limit with throttling, and the order of who stays when space runs short is the QoS class and the PriorityClass. The sign on the door is the taint, the authorization is the toleration, asking for the area by name is the node affinity, the balanced distribution of cars among garages is the topology spread, and the orderly removal from a garage under maintenance, without dropping below the minimum of ready cars, is the drain respecting the PodDisruptionBudget. Fitting the upgrade to one car at a time is the RollingUpdate, changing the version of both cars at once is the Recreate, the second ready chassis that receives the race number is the Blue/Green, and the new part only on car 1 is the canary. The base setup is the Helm chart, the adjustment sheet per circuit is the values file, and the car prepared for the weekend, with its revisions, is the release. The logistics that sizes the garage facilities is Karpenter, and the support crew called in by the list of orders is KEDA. The pass for each role is the ServiceAccount, the access it grants is the RBAC, the temporary pass from another organization is the short-lived cloud credential from IRSA and Workload Identity, and the validity with renewal before expiry is the certificate managed by cert-manager.
The rules of the basics guide still hold for the whole guide: each assembled chassis is a Pod, each garage is a node and the race number is the Service. This guide adds one: each version recorded on the specification sheet is a revision. Fitting an upgrade creates a new revision, and going back to the previous version reapplies a revision that is still stored, and that return also enters the history as a new revision.
The terms in plain words
41
The table below translates each technical term in the guide into an everyday idea, with no F1 and no jargon. You do not need to memorize it; come back to it whenever a term shows up in the text.
| Technical term | In plain words |
|---|---|
| Probe | A routine question asked every few seconds to the program to find out whether it is fine. |
| Liveness, readiness, startup | "Is it stuck?" (if so, restart); "can it serve now?" (if not, it stays out of service, without a restart); "has it finished starting?" (until then, the other questions wait). |
| Requests and limits | The guaranteed reservation of resources and the usage ceiling. Going over the memory ceiling gets the program shut down; going over the processing ceiling makes the program be slowed down. |
| OOMKill | The system forcibly shuts down a program that went over its memory limit. |
| CPU throttling | The system makes the program wait a few moments so that it does not exceed its processing quota, even if it was in a hurry. |
| QoS class | The order of who is kept when resources run short: whoever reserved everything it uses leaves last, whoever reserved nothing leaves first. |
| Availability | The fraction of time the service is answering. Having independent copies lowers the chance that all of them fail at the same time. |
| Taint | A notice stuck on the door of a computer: "only those with authorization may enter". |
| Toleration | The authorization the program carries so it can enter where there is a notice. It allows entry but does not oblige the program to go there. |
| Node affinity | The request "I want to run only on computers with this tag" (mandatory) or "I prefer" (optional). |
| Pod affinity and anti-affinity | A neighborhood rule: stay close to certain programs, or away from them. |
| Zone | A separate physical area inside the same region of the cloud provider, with its own power and network: if one zone fails, the others keep working. |
| Topology spread | The rule of distributing copies in a balanced way among computers or zones, with an agreed maximum difference. |
| Eviction | A computer that ran out of memory or space sends some programs away so it does not stop altogether. |
| PriorityClass | A number of importance that decides who stays and who leaves when space runs short. |
| Voluntary and involuntary disruption | Voluntary is an interruption that someone decides and schedules, such as emptying a computer for maintenance. Involuntary is one that happens unasked, such as a computer running out of memory or a machine taken back by the provider. Only the voluntary kind respects the minimum-copies rule. |
| Cordon and drain | Cordon is putting up a sign saying "no more newcomers". Drain is that plus asking, in an orderly way, those already there to go elsewhere, to empty the computer before maintenance. |
| PodDisruptionBudget (PDB) | A safety rule for planned maintenance: never let too many people leave at once, keeping at least N copies answering. |
| RollingUpdate | Swapping the version one copy at a time, without closing the service. |
| maxSurge and maxUnavailable | How many extra copies may exist during the swap, and how many may be out of service during the swap. |
| Recreate | Shutting down all the old copies before starting the new ones: there is a pause, but the two versions never answer together. |
| Revision and rollback | Each stored version receives a number, like the editions of a document. Going back (rollback) is reapplying an old edition, and that return also enters the list as a new edition. |
| Helm, chart and release | Helm is the cluster's app installer. The chart is the mold with fields to fill in. The release is a concrete installation of that mold, with a name and a history of revisions. |
| values | The sheet that fills in the mold (how many copies, which version), different for each environment. |
| Blue/Green | Two complete environments side by side: one serves, the other waits ready. Switching is changing the sign "service this way". |
| Canary | Showing the new version to only a small share of users and watching before widening. |
| Service mesh | A layer of doormen beside each program, able to split traffic in exact percentages and to measure everything that passes. |
| Argo Rollouts and Flagger | Tools that automate gradual releases, with metric checks between the steps. |
| Cluster Autoscaler and Karpenter | The ones that increase and decrease the number of computers in the cluster. The first works with predefined groups; the second arranges made-to-measure computers at the moment programs appear with no place to run. |
| NodePool | The rules for the kind of computer Karpenter may hire: sizes, regions, price, spending cap. |
| Spot | Computers rented at a large discount, which the provider may ask back with little notice. |
| Consolidation | Regrouping the programs onto fewer computers and returning the ones left over. |
| Queue | A list of tasks waiting to be served, in order of arrival. |
| KEDA and ScaledObject | KEDA adjusts the number of copies according to the size of a queue or another event. The ScaledObject is the form that says what to watch and between which limits to adjust. |
| Scale-to-zero | Shutting down all the copies when there is no work and starting one as soon as the first request arrives. |
| ServiceAccount | The identity badge of a program inside the cluster. |
| RBAC, Role and RoleBinding | RBAC is the table of who may do what. The Role is the list of permissions; the RoleBinding connects that list to a badge. Only rules that grant permission exist; there is no rule that forbids, and whatever was not granted is denied. |
| Least privilege | Giving each program only the permissions it needs and no more. |
| IRSA and Workload Identity | Exchanging the cluster badge for a temporary credential from the cloud provider, so the program does not keep a password of its own. |
| cert-manager, Issuer and Certificate | A certificate is a digital document that proves identity and allows an encrypted connection. The Issuer is who issues it; the Certificate is the request for the document; cert-manager requests it, stores it and renews it before it expires. |
| Secret rotation | Changing passwords and keys from time to time, keeping both valid for a period so nobody is left out. |
Where the comparison stops
10
The comparison helps fix who does what in the fine-grained operation, but it is not a perfect equivalence. These are the points where F1 stops applying for each stage:
- Stage 01: clipping corresponds well to CPU throttling, but the memory ceiling has no counterpart in F1: going over it does not slow the process down, it shuts the container down at once (OOMKill). In F1, the floor sits in the garage and the ceiling on the car; in the cluster, request and limit are the floor and the ceiling of the same resource, for the same container, on the same node. And a reset on track depends on the race engineer and the driver, while the kubelet restarts the container on its own, in seconds.
- Stage 02: the sign on the door, the order of priority and the distribution of cars among garages are decided by people, case by case; in Kubernetes, the scheduler applies taints, affinity and topology spread as exact rules to each Pod, and eviction under resource pressure is done by the kubelet automatically, ignoring the agreed minimum of ready cars (the PodDisruptionBudget).
- Stage 03: fitting an upgrade to a car takes hours, with the car stopped in the garage, and the regulations fix two cars; the RollingUpdate swaps Pods in seconds and can create temporary extra copies (maxSurge), something a team limited to two cars does not have. Also, in F1 two cars with different specifications coexist without trouble, and a joint swap is only justified when the change touches something shared, such as the pit wall data system; in the cluster, Recreate is chosen precisely because the two versions cannot answer at the same time (for example, because of a database that only one of them understands), and the price is the service being down until the new replicas come up.
- Stage 04: the base setup and the adjustment sheet are engineering documents interpreted by people; the chart is a template that, with the same values, always generates the same YAML, and Helm calculates on its own the difference from what is installed.
- Stage 05: handing the race number to another chassis only happens between sessions, with the cars stopped; in Blue/Green, both environments are on and ready at the same time, the switch of the selector takes effect in seconds for new connections, and the main risk (a database that both versions need to read) has no counterpart in a car.
- Stage 06: with two cars, the smallest possible test puts the new part on half the team, and the two cars have different drivers; the canary starts at a small fraction of traffic, such as 1% or 5%, with requests of the same kind on both versions, and with a service mesh the weight is exact, independent of the number of replicas.
- Stage 07: in a weekend, the garages are defined before the event and do not change; Karpenter creates and removes machines in the middle of operation, in seconds or minutes, paid for by the time of use, and Spot instances (cheap, but which the provider may take back with short notice) have no equivalent in F1 logistics.
- Stage 08: calling in the support crew takes hours and the number of people has a limit; KEDA starts a replica in seconds when the first event arrives, shuts all of them down when the queue stays empty for the configured time, and has no staff limit, only the declared maximum of replicas.
- Stage 09: the pass is a physical object checked by people at the entrance; the ServiceAccount is a token verified by the API Server on every request, RBAC only adds permissions (there is no prohibition rule) and the certificate is renewed by cert-manager with nobody involved.
- Stage 10: the comparison holds piece by piece, but preparing the car for a weekend involves dozens of people and days of work; in the cluster, the whole composition fits in a chart installed with one command, and the promotion with
helm upgrade --atomicundoes the change on its own if the release does not become healthy in time.
Stage 01 probes + requests/limits
Application health and resource management
The problem
It is Black Friday and the orders API of an e-commerce site hits a deadlock at 3 a.m. The process is still up, so as far as Kubernetes is concerned everything is Running, but every request gets a 500 error. On the resources side, the problem comes from another Pod: a reporting service with a memory leak consumes everything it finds on the node and brings down its neighbors, including the payments API.
These are two different failures with the same root: the cluster, without extra information, only knows whether the process exists and does not know how much each Pod may use. The tools in this stage give Kubernetes that information: probes (health probes) and requests/limits (the resource contract).
The concept
Probes. You have already seen all three in the basics guide; here the focus is on behavior under failure.
- Liveness asks "has the container frozen?". If it fails the number of times defined in
failureThreshold, the kubelet restarts the container. It is meant for unrecoverable freezes (deadlock), not for passing slowness, otherwise the app enters a cycle of restarts. If the process simply dies, what recreates the container is the Pod'srestartPolicy(the default isAlways), with no involvement of the liveness; the liveness covers the case where the process is still alive but frozen. - Readiness asks "can it receive requests?". If it fails, the Pod is removed from the Service endpoints and is not restarted. It comes back on its own when it passes again. It is what guarantees a rollout without errors for the user.
- Startup asks "has it finished starting?". Until it passes, liveness and readiness are suspended. It protects slow-booting apps that would otherwise be killed before they became ready.
Requests and limits. Every container can declare two values per resource:
- requests is what the container *reserves*. The scheduler uses this value to decide on which node the Pod fits. It is the guaranteed floor.
- limits is the ceiling it cannot exceed. Going over the memory limit makes the kernel shut down the container (OOMKill). Going over the CPU limit kills nothing: the kernel slows the process down (throttling) to keep it within the quota.
CPU is measured in millicores (100m is 0.1 CPU) and memory in bytes with binary suffixes (128Mi).
QoS class. From the combination of requests and limits comes the Pod's QoS class, which weighs on the decision of who leaves first under pressure:
- Guaranteed: all containers have requests equal to limits, for both CPU and memory.
- Burstable: at least one container declares a request or a limit, but the Pod does not qualify as Guaranteed. It uses idle slack and yields under contention.
- BestEffort: no container declares requests or limits. It is the first to be sacrificed.
A counterintuitive point: a CPU limit can worsen latency. The Linux kernel applies the limit through quotas in periods of 100 ms (CFS quota). A service with several threads can spend the whole quota of the period in a short burst and stand still until the next period, even with low average usage. Buffer publicly reported that it removed the CPU limits of latency-sensitive services and saw the p99 (the latency below which 99% of requests fall) drop significantly (the source report mentions 5 to 10 times). The practical lesson: in a cluster shared by several teams, limits provide isolation; in a latency-sensitive service, it is worth considering keeping the request and removing the CPU limit, keeping the memory limit.
Availability and signals. The availability of a service is A = MTBF / (MTBF + MTTR): the mean time between failures divided by that same time plus the mean time to recovery. With independent replicas, failure probabilities multiply: if each Pod is down 1% of the time, the chance of two Pods being down at the same time is 0.01 × 0.01 = 0.0001, that is, 0.01%, and the set reaches about 99.99% availability, as long as the failures are independent. The Service works as a "logical OR", because a single Ready Pod is enough. To know whether the service is truly healthy, Google SRE proposes the four *golden signals*: latency, traffic, errors and saturation. Probes cover errors and part of saturation; for the rest, Prometheus and Grafana are used.

Key concepts
Liveness differs from readiness
liveness restarts the container; readiness only takes the Pod out of traffic. Confusing the two causes cascading restarts.
Liveness and restartPolicy
if the process dies, the restartPolicy recreates the container; the liveness covers a process that is alive and frozen.
Startup probe
gives the app time to start before the other probes take effect.
requests and limits
requests is the reservation used for scheduling; limits is the ceiling (OOMKill on memory, throttling on CPU). Always define requests.
QoS
Guaranteed, Burstable and BestEffort; the class influences the order of eviction under pressure.
CPU throttling
the CPU limit can add latency even with low average usage, because of the CFS quota.
Availability
A = MTBF / (MTBF + MTTR); the failure probabilities of independent replicas multiply, and the availability of the set grows.
Golden signals
latency, traffic, errors and saturation.
Worked examples
To make the example executable, we use podinfo from the basics guide, which exposes /healthz and /readyz on port 9898. To check whether the tag exists in the registry, run docker manifest inspect stefanprodan/podinfo:6.14.1: if the command prints a JSON, the tag exists; if it answers no such manifest, choose another published tag.
# deploy-saude.yamlapiVersion: apps/v1kind: Deploymentmetadata:name: apispec:replicas: 3 # three copies, as in the basics guideselector:matchLabels:app: apitemplate:metadata:labels:app: api # must match the selectorspec:containers:- name: apiimage: stefanprodan/podinfo:6.14.1 # fixed version; confirm the tag with the command aboveports:- containerPort: 9898startupProbe: # protects a slow boothttpGet:path: /healthzport: 9898failureThreshold: 30 # up to 30 attemptsperiodSeconds: 10 # every 10s: up to 5min to startlivenessProbe: # frozen? restart the containerhttpGet:path: /healthzport: 9898periodSeconds: 10failureThreshold: 3 # 3 failures in a row before restartingreadinessProbe: # ready? joins the ServicehttpGet:path: /readyzport: 9898periodSeconds: 5resources:requests: # reservation used by the schedulercpu: 100mmemory: 64Milimits:memory: 128Mi # memory ceiling; no CPU limit, to avoid throttling---apiVersion: v1kind: Servicemetadata:name: apispec:selector:app: api # finds the Pods by the labelports:- port: 80targetPort: 9898
This Pod is Burstable: it has requests and a memory limit, but declares no CPU limit, so requests and limits are not equal for all resources.
Essential commands for this stage
Liveness probe failed and OOMKilled)Hands-on
- Apply
deploy-saude.yamland confirm 3RunningPods withkubectl get pods -l app=api. Run theqosClasscommand and observeBurstable. - Note down the names of two Pods from the list (
<pod-1>and<pod-2>). Turn off the readiness of the first withkubectl exec <pod-1> -- curl -s -X POST localhost:9898/readyz/disable. ObserveREADY 0/1withRESTARTS 0and one fewer endpoint inkubectl get endpoints api. - Bring down the process of the second Pod with
kubectl exec <pod-2> -- curl -s localhost:9898/panicand follow withkubectl get pods -w. ObserveRESTARTSgo up for<pod-2>. What restarted it was therestartPolicy: the process died and the kubelet recreated the container, with no involvement of the liveness. If the first/panicdoes not bring the process down, repeat it. - Apply
liveness-falha.yamland follow withkubectl get pod liveness-falha -w. ObserveRESTARTSgo up after 30 to 40 seconds, although the process remains alive, and confirm inkubectl describe pod liveness-falhathe pairLiveness probe failedandKilling. This is the liveness acting on an app that is alive and frozen. - Apply
pods-qos.yamland confirm the three classes with thecustom-columns. Observe that the class is calculated by Kubernetes from the requests and limits, without you declaring it. - Apply
pod-oom.yamland observe theOOMKilledstatus (confirm withdescribe podand look forReason: OOMKilled). - Clean up:
kubectl delete -f deploy-saude.yaml -f pods-qos.yaml -f pod-oom.yaml -f liveness-falha.yaml.
Tip: Do not put a database check in the liveness probe. If the database goes down, all replicas fail the liveness at the same time, restart together and you turn a dependency outage into a cascading failure. Check dependencies in the startup (so the app does not come up without them) and degrade gracefully afterwards; if the dependency goes missing, the readiness is the right place to reflect that.
Takeaway: Liveness restarts, readiness only takes the Pod out of traffic, and requests and limits tell the cluster how much each Pod reserves and how far it may go.
Stage 02 taints + affinity + spread
Advanced scheduling and node behavior
The problem
By default, the scheduler places a Pod on any node where it fits. This breaks in three real scenarios. A machine learning training job needs a GPU, and GPU nodes are too expensive to receive just any Pod. The three replicas of the database all end up on the same node, and a hardware fault takes down the whole service. And when a node runs out of disk because of logs, the cluster has to decide who leaves, without a critical Pod being sacrificed by chance. This stage is about controlling *where* Pods run and *how* the cluster protects itself.
The concept
Taints and tolerations: repelling. The *taint* is a mark placed on the node that says "do not schedule Pods here, unless they tolerate this mark". The *toleration* is the declaration on the Pod: "I accept that mark, I can go". A taint has a key, a value and an effect:
NoSchedule: does not schedule Pods that do not tolerate it; those already running there stay.PreferNoSchedule: avoids, but is not absolute.NoExecute: besides blocking new ones, it evicts the Pods that do not tolerate it and were already on the node (useful for emptying a node).
A crucial point: the taint only repels, it does not attract. A Pod that tolerates the GPU node's taint can go to the GPU node or to an ordinary node. To guarantee that it goes *only* to the GPU, combine it with node affinity.
Node affinity: attracting. It is the positive counterpart: "I want to go to nodes with this label". There are two modes, written in the fields requiredDuringSchedulingIgnoredDuringExecution (mandatory: without the label, the Pod stays Pending) and preferredDuringSchedulingIgnoredDuringExecution (preference, with a weight: if there is none, it is scheduled elsewhere). The IgnoredDuringExecution part indicates that the rule applies only at scheduling time; if the node's label changes later, the Pod is not moved.
Pod affinity and anti-affinity: relating Pods to each other. Instead of looking at node labels, they look at the Pods that are already there. *Affinity* brings together (cache close to the frontend, in the same zone); *anti-affinity* separates (do not put two database replicas on the same node). The zone is a separate physical area inside the same region of the cloud provider, with its own power and network. The Kubernetes documentation does not recommend using inter-pod rules in clusters of several hundred nodes, because the calculation is expensive for the scheduler.
Topology Spread Constraints: spreading with a numeric guarantee. It is the preferred alternative for distributing replicas. You declare a topologyKey (the grouping criterion, for example kubernetes.io/hostname for nodes or topology.kubernetes.io/zone for zones), a maxSkew (the maximum allowed difference in the number of Pods between two groups) and whenUnsatisfiable: DoNotSchedule (strict, the Pod stays Pending if it would violate the rule) or ScheduleAnyway (preference). With 4 replicas, 2 nodes and maxSkew: 1, the only accepted distribution is 2 and 2; 3 and 1 is rejected, because the difference would be 2.
Eviction under pressure: the node's self-protection. When the node runs out of memory, disk or PIDs, the kubelet acts before the collapse. First it tries to free space (dead containers, unused images). If that is not enough, it starts evicting Pods. The order follows the documentation: first the Pods whose usage of the scarce resource exceeds the request, then the priority (PriorityClass), then the size of the usage relative to the request. In practice, BestEffort and Burstable Pods that went over their requests leave first, and Guaranteed and high-priority Pods leave last. Details that matter:
- Eviction under resource pressure ignores the PodDisruptionBudget, because it is an emergency.
- The kubelet parameter
eviction-minimum-reclaimmakes the kubelet free a margin beyond the threshold, to avoid a domino effect of repeated evictions. - Eviction is not OOMKill. OOMKill is the kernel shutting down *a container* that went over its memory limit; eviction is the kubelet removing *Pods* to save the *node*.
Planned maintenance: cordon, drain and PodDisruptionBudget. When you need to empty a node on purpose (upgrade, machine replacement), you use kubectl cordon (marks the node as unschedulable) and kubectl drain (cordon, plus orderly eviction of the Pods). This kind of interruption, decided and scheduled by someone, is called a voluntary disruption; an interruption that happens unasked (a node out of memory, a machine taken back by the provider) is involuntary. The PodDisruptionBudget (PDB) defines how many Pods of an application may be unavailable during a voluntary disruption, in minAvailable (the minimum that must stay up) or maxUnavailable (the maximum that may leave). The drain respects the PDB: if removing a Pod would violate the budget, the eviction is refused and retried until it is possible. Eviction under resource pressure, described above, is involuntary and does not respect the PDB.
PriorityClass and the nature of the scheduler. The PriorityClass assigns a numeric priority to Pods. System Pods (system-cluster-critical and system-node-critical) have very high priority and are almost never evicted. Allocating Pods onto nodes with multiple constraints is a bin packing problem, NP-hard; the scheduler uses a greedy two-phase heuristic (it filters the nodes that fit, scores the ones left, picks the best), fast but not necessarily optimal.
Key concepts
Taint repels, affinity attracts
for strong isolation (GPU node only for ML), combine the two.
Taint effects
NoSchedule, PreferNoSchedule and NoExecute (this one evicts).
required and preferred
affinity can be mandatory (hard) or a preference with a weight (soft).
Anti-affinity and Topology Spread
both spread replicas; Topology Spread uses maxSkew and scales better.
Order of eviction
usage above the request, then priority, then usage relative to the request.
Voluntary and involuntary disruption
the first is decided by someone (drain, node upgrade) and respects the PDB; the second happens unasked and does not.
PodDisruptionBudget
limits voluntary disruptions; it does not protect against eviction under pressure.
PriorityClass
system pods have near-maximum priority.
Greedy scheduler
filters, scores and picks; it is fast, but does not guarantee the best possible distribution.
Worked examples
This example requires a node with a GPU and the NVIDIA device plugin installed, so it does not run on Minikube. The executable version comes next.
# pod-gpu.yaml# Preliminary step, done once by whoever administers the cluster:# kubectl taint nodes gpu-node-1 nvidia.com/gpu=true:NoSchedule# kubectl label nodes gpu-node-1 accelerator=nvidia-gpuapiVersion: v1kind: Podmetadata:name: treino-mlspec:tolerations: # accepts the GPU node's taint- key: "nvidia.com/gpu"operator: "Equal"value: "true"effect: "NoSchedule"affinity:nodeAffinity: # AND requires going to a node with a GPUrequiredDuringSchedulingIgnoredDuringExecution:nodeSelectorTerms:- matchExpressions:- key: "accelerator"operator: Invalues: ["nvidia-gpu"]containers:- name: treinoimage: myregistry/treino:1.0 # fictitious imageresources:limits:nvidia.com/gpu: 1 # asks the device plugin for one GPU
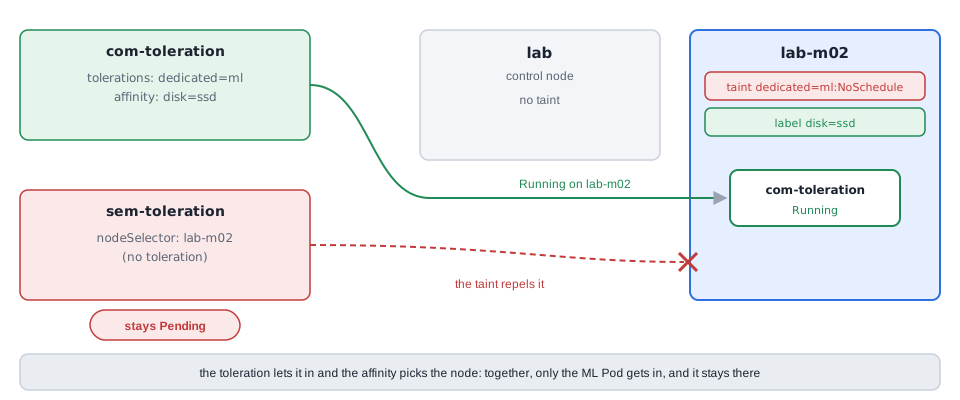
The toleration alone would leave the Pod free to land on an ordinary node. The affinity alone would not stop ordinary Pods from occupying the GPU node. Together, only the ML Pod gets in there, and only it stays there.
Essential commands for this stage
- at the end of the effect to remove it)MemoryPressure, DiskPressure, PIDPressure)Hands-on
- If the default Minikube profile is running, run
minikube stop. Bring up the 2-node cluster (minikube start -p lab --nodes 2), apply the taint and the label onlab-m02and apply the two Pods from the example. Observesem-tolerationinPendingand the messageuntolerated taintin thedescribe; observecom-tolerationinRunningonlab-m02. - Remove the taint (
kubectl taint nodes lab-m02 dedicated=ml:NoSchedule-), delete the two Pods and applyweb-spread.yamlandpdb-web.yaml. Observe with-o widethe 4 Pods split 2 and 2 and, inkubectl get pdb web, the value1inALLOWED DISRUPTIONS. - Delete
webandpdb-webwithkubectl delete -f web-spread.yaml -f pdb-web.yaml, applypdb-drain.yaml, run thedrainoflab-m02and observe the refusalCannot evict pod as it would violate the pod's disruption budget. Interrupt with Ctrl+C and runkubectl uncordon lab-m02. - Run
kubectl describe node laband observe theConditionssection:MemoryPressure,DiskPressureandPIDPressureatFalseare the healthy state. Eviction under pressure (which ignores the PDB) only happens when one of them becomesTrue; it is not reproduced here because it would require exhausting the node. - Clean up:
minikube delete -p lab. This removal also deletes thelabcontext fromkubectl, so return to the default cluster withminikube start(if you stopped the default profile in step 1) or withkubectl config use-context minikube, and confirm withkubectl get nodesbefore moving on to Stage 03.
Tip: Monitor the disk and memory usage of the nodes and alert before reaching the kubelet's eviction threshold. By default, the kubelet starts forced eviction of Pods when the free space of the node's filesystem falls below 10% (disk about 90% full) or the available memory falls below 100Mi, values that are configurable. An alert at around 80% to 85% disk usage, together with log rotation, avoids a chain of evictions. Between reacting by draining the node manually and letting the kubelet evict in an emergency, always prefer the first option.
Takeaway: Taint repels, affinity attracts, topology spread distributes with numbers, and the PodDisruptionBudget protects planned maintenance, but not eviction under resource pressure.
Stage 03 update strategies
Update strategies and rollouts
The problem
Version 2.0 of the checkout has to go live on Friday at 6 p.m., during a campaign. Two risks appear: taking the service down during the swap and mixing two versions that are not compatible with each other (for example, when 2.0 depends on a database migration that breaks 1.0). The Deployment solves both cases, with two native strategies, and provides tools to detect when the swap has stalled.
The concept
RollingUpdate (the default) replaces Pods gradually, keeping the service up. The Deployment creates a new ReplicaSet with the new version and shrinks the old one as the new Pods become ready. Two parameters control the pace of the swap:
- maxUnavailable: the capacity floor, that is, how many Pods may be unavailable during the swap. Default: 25%.
- maxSurge: the extra slack, that is, how many Pods *more* than desired may exist temporarily. Default: 25%.
With N replicas and the default values, during the rollout there are at least about 75% of Pods available and at most about 125% of Pods running. Kubernetes rounds maxSurge up and maxUnavailable down; with 10 replicas, the default results in 3 surge and 2 unavailable, that is, at least 8 available and at most 13 running. The two parameters cannot both be zero, because the swap would have no way to progress.
Recreate shuts down *all* the Pods of the old version before bringing up those of the new one. There is downtime, but the two versions never coexist. It is the choice when v1 and v2 are incompatible.
Tuning is a trade-off. A high maxUnavailable allows more Pods to be swapped at the same time, which speeds up the swap, but reduces the capacity serving users during it, and the request queue grows. In queueing theory, λ is the arrival rate of requests, μ is how much each Pod serves per second and c is the number of Pods; the utilization ρ = λ/(cμ) is the fraction of capacity in use. With fewer Pods (smaller c), ρ rises, and latency grows very fast when ρ approaches 1. A high maxSurge also speeds things up, but doubles the number of Pods and connections, and that can saturate the database. Two useful recipes:
- Availability first:
maxUnavailable: 0(never reduces capacity) andmaxSurgewithin the cluster's resource budget. - Shortest time under a budget: choose
maxSurgeandmaxUnavailableas high as possible, so that the peak of Pods ((1 + surge) × N) fits in the resource budget and the floor ((1 - unavailable) × N) does not degrade the service beyond what is acceptable.
Safeguard tools:
minReadySeconds(default 0): how many seconds a Pod must remainReadybefore it counts as available. It prevents moving ahead with a Pod that fails right after starting.progressDeadlineSeconds(default 600): if the rollout does not progress in that time, the Deployment receives the conditionProgressDeadlineExceeded. The Deployment does not roll back on its own; you do it (or a tool does).revisionHistoryLimit(default 10): how many old revisions (ReplicaSets) to keep for rollback.
The rollout is only triggered by changes in .spec.template. Changing the number of replicas or an annotation of the Deployment itself does not count.
More sophisticated strategies. Blue/Green and canary (next stages) are not native to the Deployment object. Controllers such as Argo Rollouts and Flagger implement them, with promotion steps and automatic analysis of metrics.
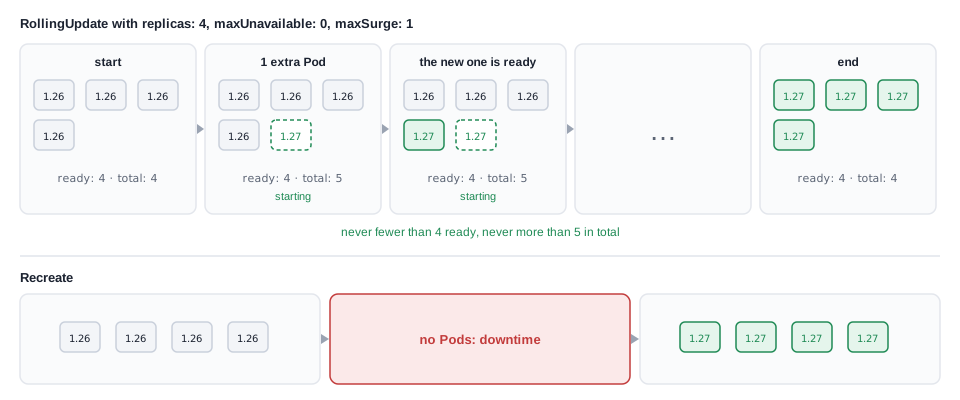
maxUnavailable: 0 and maxSurge: 1, the swap never drops below 4 ready Pods and never goes above 5 in total. Recreate keeps the versions from coexisting, at the cost of a gap with no Pod at all.Diagram: made for this guideKey concepts
RollingUpdate and Recreate
zero downtime versus total consistency at the cost of a pause.
maxSurge and maxUnavailable
maxUnavailable defines the capacity floor (how many Pods may leave) and maxSurge is the extra slack (how many more Pods may exist); defaults of 25% each, with rounding up for surge and down for unavailable.
Both set to zero
not allowed.
minReadySeconds
avoids counting as ready a Pod that may still fail.
progressDeadlineSeconds
detects a stalled rollout, without an automatic rollback.
Rollout trigger
only changes in .spec.template.
Argo Rollouts and Flagger
add canary and blue/green with automatic metric analysis.
RollingUpdate with availability first
# myapp.yamlapiVersion: apps/v1kind: Deploymentmetadata:name: myappannotations:kubernetes.io/change-cause: "nginx 1.26" # shows up in the rollout historyspec:replicas: 4minReadySeconds: 10 # the Pod must stay Ready for 10s to count as availableprogressDeadlineSeconds: 600 # default: 10 minutes for the rollout to progressrevisionHistoryLimit: 10 # default: keeps 10 revisions for rollbackstrategy:type: RollingUpdaterollingUpdate:maxUnavailable: 0 # never reduces capacitymaxSurge: 1 # creates 1 extra Pod at a timeselector:matchLabels:app: myapptemplate:metadata:labels:app: myappspec:containers:- name: appimage: nginx:1.26readinessProbe: # without readiness, the Pod counts as ready as soon as it startshttpGet:path: /port: 80
Essential commands for this stage
change-cause--to-revision=N for a specific revision)kubectl rollout resume deployment/myapp resumes itHands-on
- Apply
myapp.yamland confirm 4RunningPods. In a second terminal, runkubectl get pods -w. - Run
kubectl set image deployment/myapp app=nginx:1.27. Observe in the second terminal that there are always 4 ready Pods and that at most 1 extra Pod appears: it ismaxUnavailable: 0withmaxSurge: 1in action. - Record the change with
kubectl annotateand confirm inkubectl rollout history deployment/myappthat revision 2 showsnginx 1.27. - Shorten the deadline with the
patchofprogressDeadlineSeconds: 30, swap the image tonginx:nao-existeand runkubectl rollout status deployment/myapp. Observe the messageexceeded its progress deadlineand confirm the exit code withecho $?. - Observe with
kubectl get podsthat the old Pods are stillRunning: the service never went down. Go back withkubectl rollout undo deployment/myapp. - Clean up:
kubectl delete -f myapp.yaml.
Tip: Always fill in the kubernetes.io/change-cause annotation. Without it, rollout history shows <none> and, at the moment of an incident at 3 a.m., you do not know which revision to go back to. The --record flag, which did this automatically, is deprecated; prefer kubectl annotate or the manifest itself.
Takeaway: RollingUpdate swaps without bringing anything down, maxSurge gives slack to create extra Pods and maxUnavailable defines the capacity floor, and the Deployment only warns that the rollout stalled: undoing it is up to you.
Stage 04 packages + values
Package manager with Helm Charts
The problem
A real application has a Deployment, a Service, a ConfigMap, an HPA and a few more objects, and it exists in at least three environments: dev, staging and production. The manifests of the three environments are almost identical (perhaps 95% of the fields), and only replicas, image and resources change. Keeping three copies of the same files means someone fixes a bug in one environment and forgets the others, and it makes it hard to know what is actually installed in production and how to go back. Helm solves this: it packages the manifests into parameterized, versioned and reusable charts.
The concept
Helm works as the package manager of Kubernetes (comparable to apt or yum). A chart has a simple structure:
- `Chart.yaml`: package metadata.
versionis the version of the *chart*;appVersionis the version of the packaged *application*. Both follow SemVer, and separating them allows the chart to evolve without changing the app and vice versa. - `values.yaml`: the configurable default values (replicas, image, port, resources). Everything that varies by environment lives here; each environment uses its own values file, with
-f. - `templates/`: the manifests written as Go language templates, with Sprig functions.
{{ .Values.replicaCount }}inserts a value; files such as_helpers.tplgather reusable snippets (names and labels).
A Helm template behaves like a function: given the same values, it produces the same YAML, and you check the result before applying with helm template. This gives predictability and makes testing possible. Functions such as lookup, now and randAlphaNum break this rule (they read the cluster or generate different values on each run), so use them consciously.
The life cycle of a release. Each installation of a chart is a release, with a name and a history:
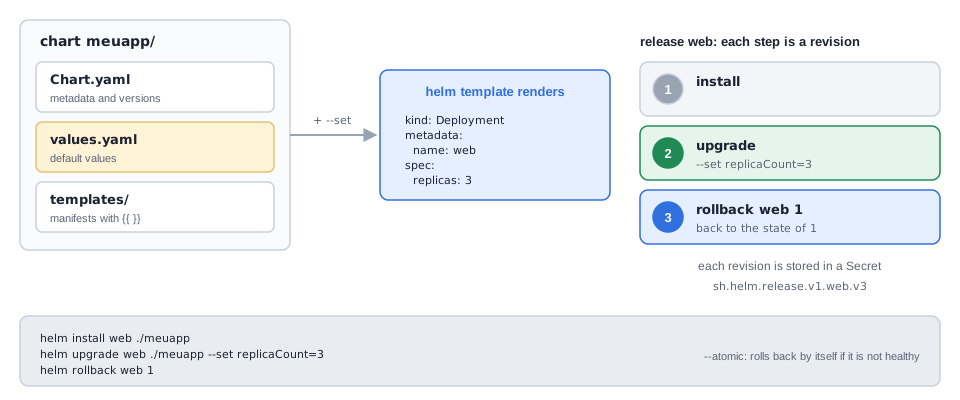
helm installcreates the release and records the state as a Secret in the namespace (sh.helm.release.v1.<name>.v<revision>).helm upgraderenders the templates again, calculates the differences from what is installed, applies only what changed and creates a new revision. Runninghelm upgradewithout changing anything does not alter the cluster's resources, but Helm records a new revision anyway.helm rollback <release> <revision>goes back to the state of an earlier revision, and the rollback also generates a new revision. The old revisions are not altered, and that is what makes the rollback reliable.
Helm 3 has no central server (the old Tiller was removed). The client uses the credentials of your kubeconfig, so the user's RBAC limits what Helm can do.
Governance at scale. Charts follow SemVer (a major version change indicates a break and calls for human review), are distributed through repositories (Artifact Hub, private repositories) and can be signed (GPG, with a .prov file), which protects the supply chain. A chart should embed least-privilege RBAC (dedicated ServiceAccounts, limited Roles). Subcharts allow composition (an "umbrella" chart that joins the app and the database), and values.schema.json validates the values like a type schema. In GitOps flows (Argo CD, Flux), the chart lives in Git, synchronization is automatic and each release becomes an auditable commit.
Key concepts
Chart, values, templates
reusable package, parameters and parameterized manifests.
version and appVersion
chart version and app version; both SemVer.
Template
given the same values, generates the same YAML; check with helm template.
Release and revision
each install, upgrade and rollback generates a revision; the history is kept in Secrets.
Helm 3 and RBAC
no Tiller; Helm only does what the user can do.
--atomic
automatically reverts the upgrade if the release does not become healthy in time.
Governance
SemVer, repositories, signing (.prov), minimal RBAC and values.schema.json.
A minimal chart, from scratch
Install Helm (helm.sh/docs/intro/install) and confirm with helm version. Create the folder meuapp/ with three files.
# Chart.yamlapiVersion: v2 # version of the Helm 3 chart formatname: meuappdescription: Chart de estudotype: applicationversion: 0.1.0 # chart versionappVersion: "1.26" # version of the packaged application (informational)
Essential commands for this stage
Hands-on
- Create the folder
meuapp/with the three files, runhelm lint ./meuappandhelm template web ./meuapp --set replicaCount=3. Observereplicas: 3in the rendered YAML: the values were overridden without touching the file. - Run
helm install web ./meuappandkubectl get secret -l owner=helm. Observe the Secret that holds revision 1. - Run
helm upgrade web ./meuapp --set replicaCount=3, thenhelm rollback web 1andhelm history web. Observe that the rollback created a new revision (number 3) instead of erasing number 2. - Run the upgrade with
--set image.tag=nao-existe --atomic --timeout 30s. Observe the errorUPGRADE FAILED ... rolled backand thatkubectl get deploy webstill shows the old Pods healthy. - Clean up:
helm uninstall web.
Tip: Run helm diff upgrade (the helm-diff plugin, installed with helm plugin install https://github.com/databus23/helm-diff) before applying in production. Seeing what will change in the cluster removes the insecurity of applying a template "blindly", a common complaint from those starting with Helm.
Takeaway: Helm turns repeated manifests into a chart with values per environment, records each change as a revision and lets you go back with a single command.
Stage 05 whole-environment switch
Blue/Green deployment
The problem
The rolling update from Stage 03 mixes versions during the swap: for a few minutes, part of the users see v1 and part see v2. For a big change in the checkout, this is unacceptable, and going back in case of error takes time, because the cluster has to swap the Pods again. It would be better to have the new version already ready, tested, waiting, and to switch everything at once, with the possibility of going back in seconds. That is the idea of Blue/Green.
The concept
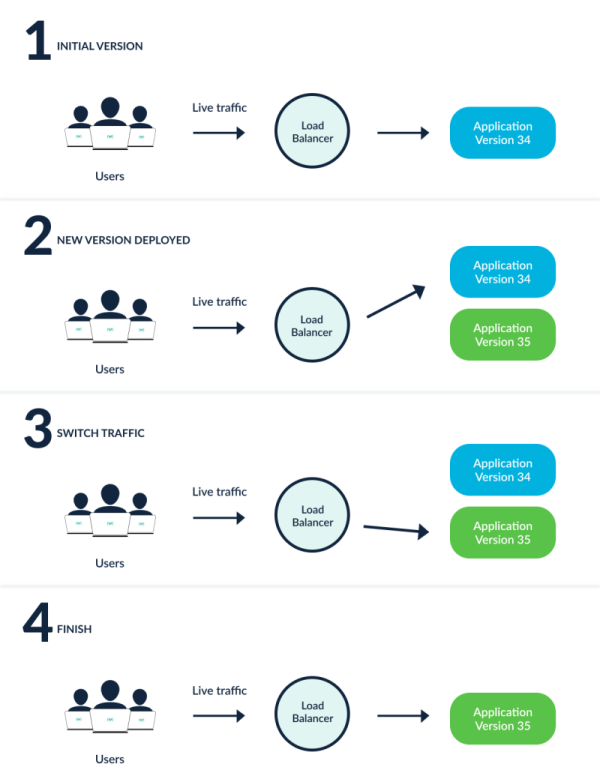
You keep two identical production environments. Blue is the current version, serving 100% of the traffic. Green is the new version, with all Pods ready, but without traffic. When Green is validated, you switch the traffic to it. If there is a problem, you switch back.
In Kubernetes, the two sets of Pods are two Deployments, with different labels (env: blue and env: green, besides the common app). A Service points to one of them through the selector. The promotion is a patch on the Service's selector: the endpoints controller recalculates the Service's list of Pods and kube-proxy reconfigures the routing. The rollback is the inverse patch. Since the old Pods are still up (just without traffic), going back requires no redeployment. A practical note: the switch applies to new connections; connections that are already open (for example, HTTP keep-alive) may stay on the old Pods until they are closed.
Formally, it is a transition from one state to another with a single operation, and the rollback is the same operation in the opposite direction. If v2 fails, the damage is limited to the time until detection: reverting at once reduces that time to the minimum.
Pitfalls:
- Data and schema compatibility. It is the biggest practical challenge. If Green alters the database in an incompatible way, going back to Blue breaks. The solution is to make the change in two phases (a pattern known as expand/contract): first migrate the database to support *both* versions, validate, and only then switch the code. Without this, data written by Green can render Blue unusable.
- Cost. Two complete environments mean about 100% of extra capacity during the transition. Good practice: reduce the idle environment to zero replicas after the new version stabilizes.
- Connection storm and cold cache. Switching 100% of the traffic at once suddenly throws the whole load onto Green, and cold caches can generate a spike. One mitigation is to warm Green up with shadow traffic beforehand.
Classic antipattern: failing to treat Green as production all the time. If you accumulate changes waiting for the "right moment" to switch, the jump between versions becomes large and risky. True Blue/Green means deploying continuously to the idle environment and flipping the switch when there is confidence.
Tools. Argo Rollouts supports blueGreen natively (with a preview service and promotion that is manual or automatic by metrics); Flagger integrates with a service mesh. The pattern is also called Red/Black in contexts such as Netflix and Spinnaker.
Key concepts
Two identical environments
only one serves traffic at a time.
The switch is a patch on the Service's selector
routing changes in seconds for new connections.
Fast rollback
the old Pods stay ready; the inverse patch is enough.
Schema compatibility
migrate the database in a backward-compatible way before switching the code.
Cost
about 100% of extra capacity during the transition; reduce the idle environment afterwards.
Green is continuous production
otherwise the jump becomes a risky big bang.
All or nothing
if you want it progressive, it is a canary (next stage).
A Service that points to blue and then to green
We use the image hashicorp/http-echo, which answers with the text passed in -text, to see which version is serving.
# bluegreen.yamlapiVersion: apps/v1kind: Deploymentmetadata:name: myapp-bluespec:replicas: 2selector:matchLabels:app: myappenv: bluetemplate:metadata:labels:app: myappenv: blue # identifies the environmentspec:containers:- name: appimage: hashicorp/http-echo:1.0args: ["-text=blue v1"] # answers with this text, on port 5678ports:- containerPort: 5678---apiVersion: apps/v1kind: Deploymentmetadata:name: myapp-greenspec:replicas: 2selector:matchLabels:app: myappenv: greentemplate:metadata:labels:app: myappenv: greenspec:containers:- name: appimage: hashicorp/http-echo:1.0args: ["-text=green v2"]ports:- containerPort: 5678---apiVersion: v1kind: Servicemetadata:name: myapp-servicespec:selector:app: myappenv: blue # the key: switch to green on promotionports:- port: 80targetPort: 5678
Essential commands for this stage
selectorHands-on
- Apply
bluegreen.yaml, runkubectl get endpoints myapp-serviceand thewgetthrough theclientePod. Observeblue v1and only the 2 IPs of the blue Pods. - Do the promotion with the
kubectl patchfrom the example and query again. Observegreen v2and the 2 IPs of the green Pods inget endpoints, without any Pod having been created or removed. - Do the rollback with the inverse patch and observe
blue v1back, because the blue Pods kept existing. - Scale
myapp-blueto 0, runkubectl get endpoints myapp-serviceand observe that, with the selector on blue, the Service was left without endpoints (<none>). This is why the shutdown of the old environment should only be done after promoting and stabilizing the new one. - Clean up:
kubectl delete -f bluegreen.yaml.
Tip: Before flipping the switch, confirm that the database accepts both versions. The question is always this one: "if I need to go back to Blue in 5 minutes, will the data that Green wrote break Blue?". If the answer is yes, the cutover is not ready yet.
Takeaway: Blue/Green keeps two versions ready and switches traffic with a patch on the Service's selector, and the reversal is only safe if the database accepts both versions.
Stage 06 progressive traffic
Canary deployment
The problem
Blue/Green switches 100% of the traffic at once. If v2 has a defect that only appears with real traffic (a rare error, a slow query with production data), all users feel it at the same time, even if you can go back in seconds. It would be better to expose v2 to a small fraction of users, measure the result and only widen it if everything is fine. That is the canary deployment.
The concept
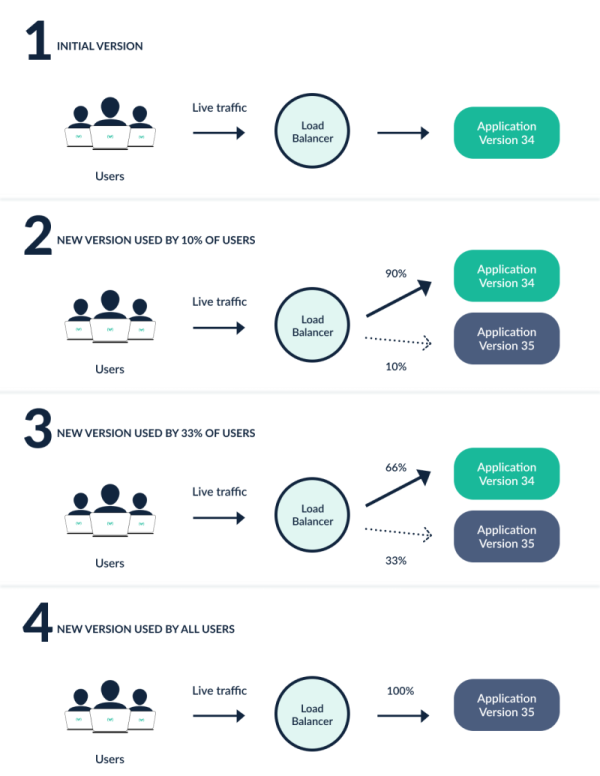
In a canary, you keep both versions running and shift the traffic gradually (for example, 1%, 5%, 25%, 50% and 100%), validating real metrics at each step. If something degrades, the impact was restricted to the few percent and you revert. In contrast, Blue/Green is "all or nothing"; the canary is progressive.
Two ways to split the traffic:
- By replica ratio, natively. Two Deployments with a label in common (for example
app: myapp), and a Service that selects only by that label. The Service distributes requests among all the Pods, so 4 stable Pods and 1 canary result in about 20% of the traffic on the canary. It is simple, requires nothing beyond Kubernetes, but the granularity depends on the number of replicas (for 1% you would need 100 Pods). - By weight, with a service mesh or an ingress that supports weights. With Istio or Linkerd, or with a compatible ingress controller, you define exact percentages (for example 90% and 10%), independent of the number of replicas. In Istio, a
VirtualServicesplits the traffic between *subsets* (v1 and v2), which are declared in aDestinationRulefrom the Pods' labels.
Metric-driven decision. What decides whether to promote or revert are real-time metrics: error rate (5xx), latency (p95 and p99, the latencies below which 95% and 99% of requests fall), resource usage, business metrics. This closes a feedback loop that can be automated: if the canary's error stays below the threshold, the weight increases; if it violates it, it goes back to v1.
Tools. Argo Rollouts and Flagger implement the steps (weights, pauses, analyses) as Kubernetes objects. In Argo Rollouts, the Rollout object replaces the Deployment and declares the strategy in steps. Without a configured traffic router (trafficRouting), the setWeight is approximated through the number of replicas, the same as the native technique; with Istio or a compatible ingress, the weight is exact.
Theory vocabulary, to know it exists:
- Continuous A/B testing: the canary is a statistical experiment between v1 (control) and v2. The null hypothesis is "there is no difference"; it is evaluated with significance tests (z-test of proportions, chi-squared, Mann-Whitney). Kayenta, used with Spinnaker at Netflix, performs canary analysis with the Mann-Whitney test.
- Sequential testing (Wald's SPRT): evaluates continuously and stops early when there is enough evidence to promote or abort, reducing user exposure.
- Queueing theory: even 10% of the traffic can degrade latency if those 10% nearly saturate the few Pods of v2. The waiting time grows very fast near saturation, which also serves to estimate whether v2 can handle 100%.
- Multi-armed bandits (Thompson Sampling): allocate traffic adaptively, balancing testing and favoring the best version.
Reported cases. The source material mentions Shopify (about 5% of the traffic for a few minutes, with automatic analysis before going to 100%), Netflix (automated canary analysis with Kayenta in Spinnaker) and Nubank (feature flags combined with canary). The exact numbers come from the original report and were not verified here. The trend is to guide the canary by SLOs (brake if the error target is violated).
Key concepts
Canary
progressive rollout with metric validation at each step.
Blue/Green versus canary
all at once versus gradual and observable.
Replica ratio
native technique, granularity limited by the number of Pods.
Weight-based routing
via service mesh or ingress; independent of the number of replicas.
Data-driven decision
error, p95, p99 and SLOs; promotion or reversal can be automatic.
Canary analysis
statistical test between baseline and canary (Kayenta); works as an automatic gate.
Argo Rollouts and Flagger
implement steps and analysis as cluster objects.
Worked examples
# canario.yamlapiVersion: apps/v1kind: Deploymentmetadata:name: myapp-stablespec:replicas: 4 # 4 of 5 Pods: about 80% of the trafficselector:matchLabels:app: myapptrack: stabletemplate:metadata:labels:app: myapp # common label, used by the Servicetrack: stable # label that distinguishes the versionspec:containers:- name: appimage: hashicorp/http-echo:1.0args: ["-text=v1 estavel"]ports:- containerPort: 5678---apiVersion: apps/v1kind: Deploymentmetadata:name: myapp-canaryspec:replicas: 1 # 1 of 5 Pods: about 20% of the trafficselector:matchLabels:app: myapptrack: canarytemplate:metadata:labels:app: myapptrack: canaryspec:containers:- name: appimage: hashicorp/http-echo:1.0args: ["-text=v2 canario"]ports:- containerPort: 5678---apiVersion: v1kind: Servicemetadata:name: myappspec:selector:app: myapp # without the "track" label: the Service sees both Deploymentsports:- port: 80targetPort: 5678
Essential commands for this stage
kubectl argo rollouts abort myapp abortsHands-on
- Apply
canario.yamland runkubectl get endpoints myapp. Observe the 5 endpoints (4 stable and 1 canary). - Run the 20-request loop with the
clientePod. Observe the approximate count of 80% forv1 estaveland 20% forv2 canario. Run it again and observe that the numbers change: the split is statistical, not exact. - Abort the canary with
kubectl scale deployment myapp-canary --replicas=0and repeat the loop. Observe that onlyv1 estavelanswers. - Reflect on the limit of the technique: for a 1% canary, how many replicas would be needed? That is the reason service meshes and Argo Rollouts with weight-based routing exist.
- Clean up:
kubectl delete -f canario.yaml.
Tip: Tie the canary to your SLOs, not to arbitrary metrics. If the error SLO is 0.1%, the canary should stop automatically when v2 violates that limit. That way, production monitoring and deploy monitoring become the same thing, and the decision to promote stops being subjective.
Takeaway: The canary exposes the new version to a fraction of the traffic and only advances with good metrics; without a service mesh the fraction depends on the number of replicas, and with one the weight is exact.
Stage 07 node scaling
Node scalability with Karpenter
The problem
The previous stages scale Pods. But on Black Friday, when the HPA asks for 30 more replicas, the whole cluster is already full: the new Pods stay Pending, because there is no node with free CPU and memory. The number of nodes needs to increase. The traditional Cluster Autoscaler does this, but it works with fixed groups of nodes (for example, AWS Auto Scaling Groups), preconfigured by instance type and by zone, which is laborious to maintain and slow to react. A small Pod can trigger a large node, and the node sits idle.
The concept
Karpenter (created by AWS, open source, with providers for other clouds) provisions nodes on demand, sized for the Pods that are pending, without fixed groups. It reacts in seconds to a few minutes, chooses the most suitable instance type (including Spot) and removes idle nodes on its own. Companies report savings of up to 30% in compute cost, a figure that depends on the environment.
The provisioning flow:
- Pods become unschedulable: the scheduler did not find a node (
Pending, with the eventFailedScheduling). - Karpenter observes these Pods and adds up their resource requests.
- It calculates which instance type best accommodates the set, within the rules of the NodePool.
- It provisions the node (through a
NodeClaim), and the Pods are scheduled on it.
The inverse flow, consolidation: Karpenter identifies underused nodes, moves the Pods to other nodes and removes the node that is left over, or swaps an expensive instance for a cheaper one. Consolidation waits a configurable time (consolidateAfter) before acting, so as not to react to short oscillations.
Configuration in two objects:
- NodePool: defines the rules for the nodes Karpenter may launch (allowed instance types, zones, Spot or On-Demand, resource limits). Older versions called this object a Provisioner. The recommendation is to restrict as little as possible, to give freedom for optimization.
- EC2NodeClass (on AWS): defines what is provider-specific (AMI, subnets, security groups, the nodes' IAM role). The NodePool points to it through
nodeClassRef.
The underlying problem is multidimensional bin packing (each Pod is an item with a vector of CPU and memory, and each node is a container), which is NP-hard. Karpenter uses a greedy heuristic: it discards types that do not fit (no GPU when the Pod asks for a GPU, wrong zone), sorts by cost and suitability and looks for a solution with little leftover, similar to First-Fit Decreasing. The key difference from the Cluster Autoscaler is right-sizing: a small node for a small Pod, a large node when large Pods arrive, mixing types as needed.
Costs and Spot. Spot instances cost much less than On-Demand (on the order of 70% to 90% discount, depending on the type and the moment), but the provider may take them back with short notice (2 minutes on AWS). Karpenter handles this with proactive interruption: it detects the notice, marks the node as terminating, applies a taint and drains the Pods to another node before the cutoff. Two important precisions:
- For voluntary disruptions (consolidation, drift, expiration), Karpenter respects PodDisruptionBudgets and does not bring down Pods beyond what the budget allows.
- The Spot interruption is involuntary: the provider will take the machine back anyway, and the 2-minute deadline may not be enough to drain everything. That is why the PDB reduces the risk but does not eliminate it.
Good practices: a PDB to limit how many Pods leave together, Topology Spread to distribute replicas across nodes and zones, and separate NodePools for critical workloads (On-Demand) and interruption-tolerant workloads (Spot).
Reported cases. The source material mentions Mercado Livre (use of Karpenter to mix instance types and use Spot and reserved capacity, eliminating dozens of node groups) and Tinybird (a cut of about 20% of the AWS bill, 90% in the CI environment, by consolidating everything into two NodePools: one critical On-Demand and one stateless 100% Spot). The numbers come from the original report.
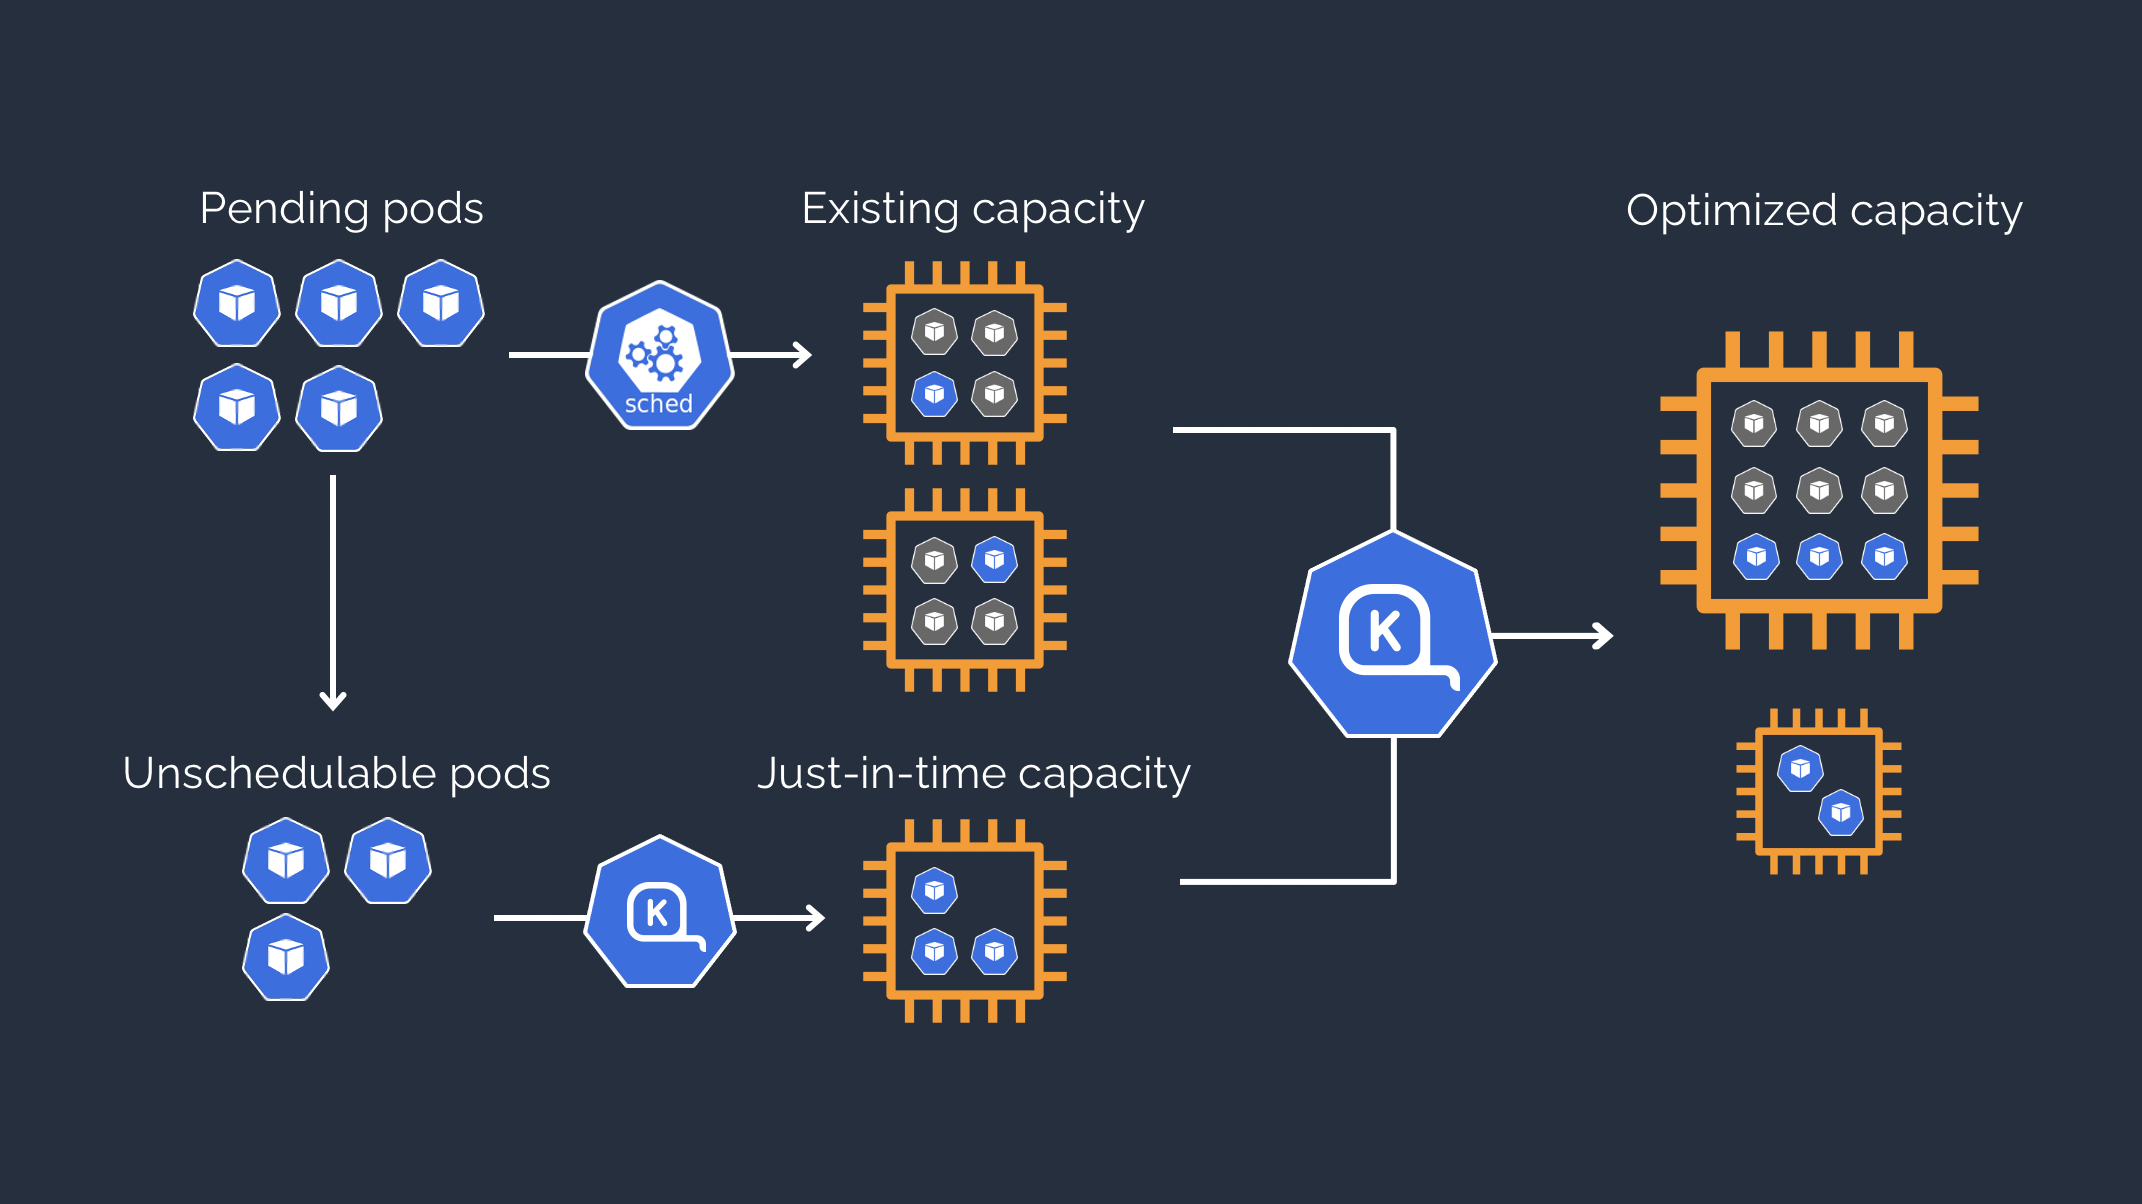
Pending Pod with FailedScheduling, the same one you trigger in the lab. It creates a node of the required size and later consolidates idle or underused nodes.Diagram: karpenter.sh, Karpenter project, Apache 2.0Key concepts
Karpenter
on-demand node autoscaling, sized for the pending Pods, without fixed groups.
Cluster Autoscaler versus Karpenter
fixed groups and slower, against flexible, fast and with right-sizing.
NodePool and EC2NodeClass
rules for the nodes (types, zones, Spot, limits) and provider details; restrict as little as possible.
NP-hard bin packing
Karpenter uses a greedy least-waste heuristic.
Consolidation
removes or swaps idle nodes, with a configurable wait (consolidateAfter).
Spot
much cheaper; proactive interruption with drain; respects the PDB in voluntary disruptions, but the Spot interruption is involuntary.
Isolate workloads
distinct NodePools for critical load (On-Demand) and tolerant load (Spot).
Worked examples
It requires an EKS cluster with Karpenter installed. The names of the cluster, the role and the tags are placeholders; the example is meant for reading.
# nodepool.yamlapiVersion: karpenter.sh/v1kind: NodePoolmetadata:name: defaultspec:template:spec:requirements:- key: karpenter.sh/capacity-typeoperator: Invalues: ["spot", "on-demand"] # allows both; Karpenter prioritizes Spot when possible- key: kubernetes.io/archoperator: Invalues: ["amd64"]nodeClassRef: # in v1 the nodeClassRef needs group, kind and namegroup: karpenter.k8s.awskind: EC2NodeClassname: defaultlimits:cpu: "1000" # ceiling of the combined CPU of the nodes in this NodePoolmemory: 1000Gidisruption:consolidationPolicy: WhenEmptyOrUnderutilized # consolidates empty or underused nodesconsolidateAfter: 30s # waits 30s before acting---apiVersion: karpenter.k8s.aws/v1kind: EC2NodeClassmetadata:name: defaultspec:role: "KarpenterNodeRole-meu-cluster" # the nodes' IAM role (placeholder)amiSelectorTerms:- alias: al2023@latest # Amazon Linux 2023 AMIsubnetSelectorTerms:- tags:karpenter.sh/discovery: meu-cluster # discovers the subnets by tagsecurityGroupSelectorTerms:- tags:karpenter.sh/discovery: meu-cluster
Essential commands for this stage
Hands-on
- Apply
pod-grande.yamlon Minikube and runkubectl get pods. Observe the Pod inPending. - Run
kubectl describe pod -l app=grandeand observe in Events the messageFailedSchedulingwithInsufficient cpu. This is the signal Karpenter uses to decide to create a node. - Run
kubectl get nodes -L karpenter.sh/capacity-typeand observe the empty column: no node was provisioned by Karpenter, which confirms it is not installed. - Read the NodePool from the example and answer: what happens if
limits.cpuis reached? (Answer: Karpenter does not create new nodes in that NodePool and the Pods stayPending.) - Clean up:
kubectl delete -f pod-grande.yaml.
Tip: Run stateless, interruption-tolerant workloads on Spot, and reserve On-Demand for what is critical or stateful, in separate NodePools. Combine with a PodDisruptionBudget and Topology Spread, so that a Spot interruption never takes down too many replicas of the same service at the same time.
Takeaway: Karpenter creates made-to-measure nodes when there are Pods with no place to run and removes idle ones, and Spot is only safe with a PDB and topology spread, because the Spot interruption is involuntary and can arrive before the drain finishes.
Stage 08 event-driven scaling
Application scalability with KEDA
The problem
The default HPA scales by CPU and memory. But consider an e-commerce site with workers that process orders from a queue: when 5 thousand orders enter the queue during a flash sale, the workers may not even be using much CPU (they are waiting on I/O), so the HPA does not react, and the queue grows. In the small hours, the queue is empty and yet there are workers running, spending resources. What is missing is a way to scale by queue size, and even down to zero when there is no work.
The concept
KEDA (Kubernetes Event-driven Autoscaler) scales based on external events: queues (RabbitMQ, SQS, Kafka, Redis), Prometheus metrics, cron, among others, and supports scale-to-zero.
The central object is the ScaledObject. It points to a target Deployment and defines one or more triggers. How it works in practice:
- KEDA queries the trigger's source every
pollingIntervalseconds. - Empty queue: keeps the Deployment at 0 replicas (if
minReplicaCount: 0). - An event arrives: KEDA activates the Deployment (from 0 to 1).
- From 1 on, what calculates the number of replicas is an HPA that KEDA itself creates: for example, with
value: "10"inQueueLengthmode, 40 messages result in 4 Pods. - The queue becomes empty and stays that way for
cooldownPeriodseconds: KEDA takes the Deployment back to 0.
Three points of precision. First, the HPA alone cannot go to zero (the minimum is 1), so the activation from 0 to 1 and the return to 0 are KEDA's responsibilities. Second, the cooldownPeriod (default 300 seconds) counts the time during which the trigger is inactive (empty queue) and only applies to the move to zero. Third, the difference between the two ways of scaling down: when the trigger becomes inactive, KEDA zeroes the Deployment directly, from any number of replicas (from 4 to 0, for example), at the end of the cooldownPeriod; the HPA's scale-down stabilization window (default 5 minutes, adjustable in the ScaledObject under advanced.horizontalPodAutoscalerConfig.behavior), on the other hand, applies to reductions while the queue is still active, such as going from 5 to 3 replicas with the queue shrinking but still holding items.
Queueing theory. Calling λ the arrival rate of events and μ the rate at which each Pod processes, with c Pods the capacity is c·μ. The stability condition is λ < c·μ: if arrivals are sustainedly greater than the capacity, the queue grows without limit and no autoscaling solves it. Little's Law (L = λ·W) relates the average number of items in the system L, the arrival rate λ and the average time in the system W: if the backlog grows with constant λ, W is increasing, that is, there are not enough Pods.
Oscillation. A control challenge is to avoid the up and down of replicas, caused by feedback delay (a new Pod takes time to become ready) and by fixed thresholds. Mechanisms that the HPA and KEDA offer: a tolerance (the default HPA only reacts when the metric exceeds about 110% or falls below about 90% of the target, a margin of 10%), stabilization windows and the cooldownPeriod. A general control concept is the dead band (scale up at one threshold and down at another, lower one); it illustrates the idea of hysteresis, but it is not a direct configuration of the HPA or KEDA, which use tolerance and windows. Since queues absorb bursts, a temporary backlog is accepted while the new Pods come up.
KEDA is provider-independent (AKS, EKS, GKE, on-premises) and complements the HPA, without replacing it. A typical case: order workers scaled by the SQS or Service Bus queue during flash sales, returning to zero in the small hours. For event sources that KEDA does not support, there are external scalers via gRPC.
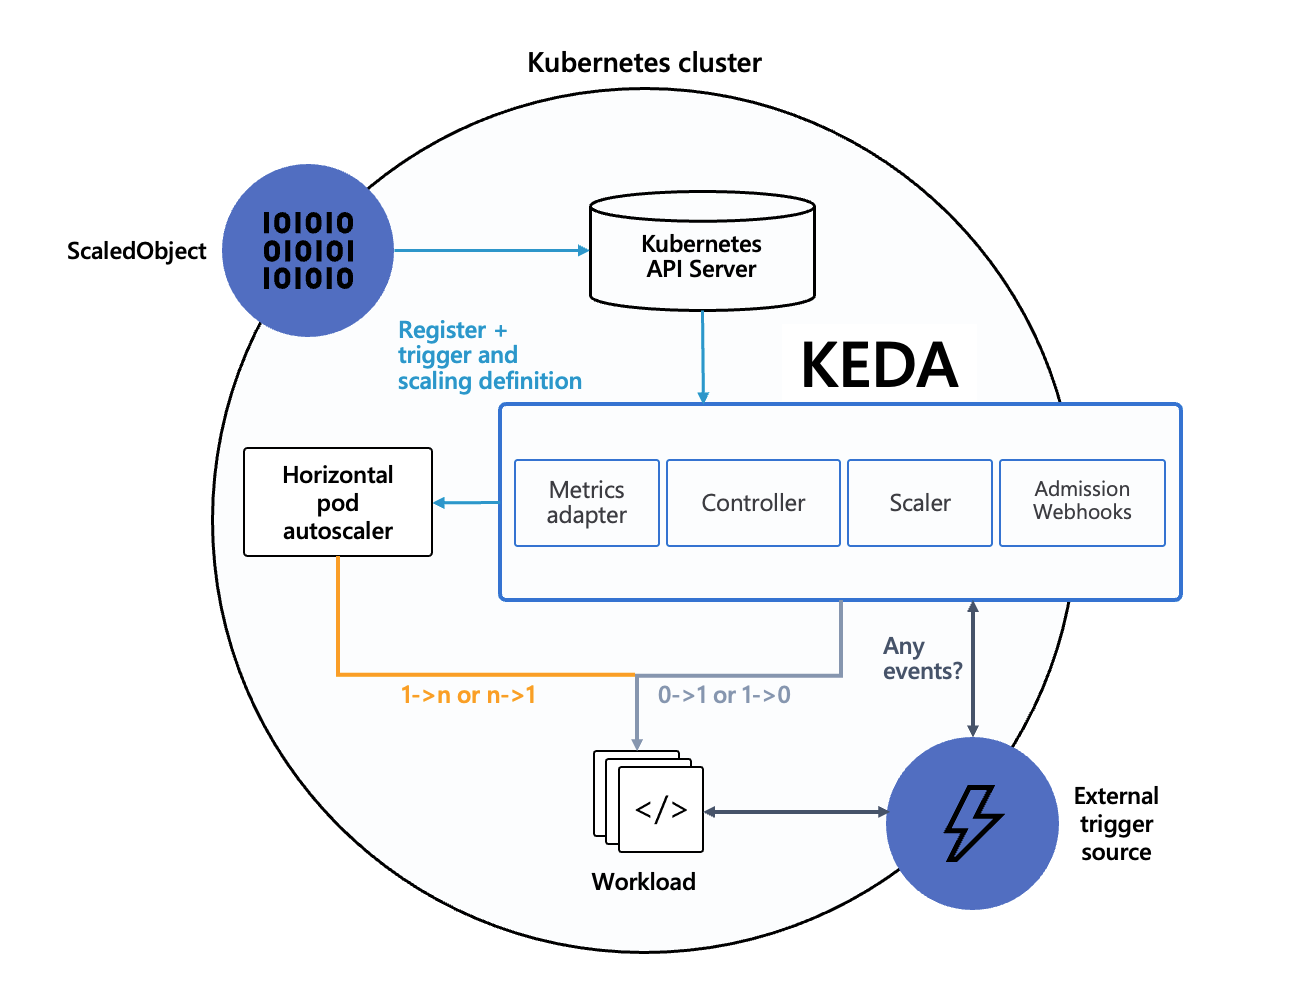
cooldownPeriod, not the HPA window.Diagram: keda.sh, The KEDA Authors, Apache 2.0Key concepts
KEDA
event-driven autoscaling (queues, metrics, cron); complements the HPA.
Scale-to-zero
KEDA starts the Deployment on the first event and shuts it down after the cooldownPeriod with the trigger inactive, from any number of replicas.
ScaledObject
the central object (target, triggers, minimum and maximum replicas, intervals).
cooldownPeriod and the HPA window
the first governs the move to zero with an empty queue; the HPA's 5-minute window governs reductions with the queue still active.
Queueing theory
stability with λ < c·μ; Little's Law L = λ·W.
Oscillation
contained with tolerance (about 10%), stabilization windows and cooldownPeriod.
Dead band
a general control concept; it is not a field of the HPA or of KEDA.
Cloud-independent
extensible with external scalers via gRPC.
Worked examples
It requires a RabbitMQ reachable from the cluster; it is meant for reading.
# scaledobject-rabbitmq.yamlapiVersion: keda.sh/v1alpha1kind: ScaledObjectmetadata:name: worker-scalerspec:scaleTargetRef:name: worker # target DeploymentminReplicaCount: 0 # allows scale-to-zeromaxReplicaCount: 5cooldownPeriod: 60 # queue empty for 60s before going to zeropollingInterval: 15 # queries the queue every 15striggers:- type: rabbitmqmetadata:queueName: pedidosprotocol: amqpmode: QueueLength # scales by the queue sizevalue: "10" # one Pod for every 10 messageshostFromEnv: RABBITMQ_URL # variable with the broker's URL, defined in the target Deployment's container
Essential commands for this stage
keda-hpa-)Hands-on
- Install KEDA with Helm and apply
keda-lab.yaml. Runkubectl get scaledobjectand observeREADY TrueandACTIVE False(no work). - Run
kubectl get deployment workerand observe0/0: the worker went to zero, something the HPA alone does not do. - In a second terminal, run
kubectl get deployment worker -w. In the first, push 20 items withLPUSH. Observe the number of replicas rise to 4, and check withkubectl get hpathe HPA created by KEDA. - Delete the queue with
redis-cli DEL filaand observe the Deployment go from 4 replicas straight to 0 after about 30 seconds (the exercise'scooldownPeriod). This is faster than the HPA's 5 minutes of stabilization because, with the queue empty, the trigger becomes inactive and KEDA zeroes the Deployment without going through the gradual descent; the HPA's window would only apply if the queue were shrinking but still holding items. - Push 100 items and observe the limit
maxReplicaCount: 5: even with the queue asking for 20 Pods, KEDA respects the ceiling. - Clean up:
kubectl delete -f keda-lab.yamlandhelm uninstall keda -n keda.
Tip: Adjust pollingInterval and cooldownPeriod to the dynamics of your load. A cooldown that is too short takes down good Pods in the middle of an intermittent burst; a cooldown that is too long wastes resources. And remember: if λ ≥ c·μ in a sustained way, no autoscaling solves it, because the bottleneck is the capacity or the code, and not the number of Pods.
Takeaway: KEDA scales by the event (queue, metric, cron), starts and stops the Deployment with scale-to-zero and hands the rest to the HPA, but nothing makes up for a load that is permanently greater than the capacity.
Stage 09 rbac + identity + tls
Cluster security
The problem
A real cluster runs dozens of services from several teams. If one of them is compromised (a vulnerable dependency, an image with a flaw), the attacker gains what that Pod has: the ServiceAccount token, its permissions and any cloud credentials lying nearby. If all Pods use the same generic identity, with broad permissions, the attacker reaches the whole cluster. A known incident (Tesla, 2018) combined a Kubernetes dashboard left open without a password with AWS credentials inside a Pod, and ended in cryptocurrency mining on the company's account. The defense is to limit the damage in advance, with three pillars: identity (ServiceAccounts), authorization (least-privilege RBAC) and encryption (automated TLS), under the *Zero Trust* philosophy: nothing is trusted by default.
The concept
Identity: ServiceAccounts. Each application should have its own ServiceAccount, never the namespace's default. The ServiceAccount gives the Pod a token to talk to the API Server. Separate identities per application make it possible to contain the damage when a Pod is compromised. If the application never talks to the API Server, turn off even the mounting of the token with automountServiceAccountToken: false.
Authorization: RBAC. Permissions are granted by Roles (restricted to a namespace) or ClusterRoles (cluster-wide) and tied to subjects by RoleBindings (or ClusterRoleBindings). The model is a graph: subject, binding, role and permission. Least-privilege rules:
- Prefer Role (namespaced) over ClusterRole.
- Grant only the necessary verbs (
get,list) and only the necessary resources. - Avoid the wildcard
*in verbs and resources.
Kubernetes RBAC is additive: only rules that grant permission exist, there are no denial rules, and what was not granted is denied. This makes it auditable: it is possible to list deterministically who can do what. ABAC (attribute-based) is more expressive, but opaque, and it is a legacy mechanism, rarely used. For conditional policies ("deny a Pod without limits", "only accept images from a certain registry"), an admission mechanism such as OPA/Gatekeeper is used, with the Rego language (policy as code), or Kubernetes' native admission policy features. The more expressive the policy, the harder it is to prove its properties.
Federated identity with the cloud. Applications need to access S3, buckets and secret vaults without embedding static keys in the container. The solution is to federate the Kubernetes ServiceAccount with a cloud identity through OIDC, receiving short-lived credentials:
- IRSA (IAM Roles for Service Accounts) on EKS: the ServiceAccount receives an annotation with the ARN of an IAM Role. Each application has its own Role, with the minimum necessary. (EKS also offers EKS Pod Identity as a more recent alternative.)
- Workload Identity on GKE and AKS: the ServiceAccount is associated with a cloud identity (a service account on GKE, a managed identity on AKS).
This eliminates static secrets and restricts the credential to the Pod's context. The same principle holds for IAM: the attack known as SCARLETEEL (2023, documented by Sysdig) used credentials obtained from containers to move around cloud environments, and the episode reinforces the lesson of keeping IAM permissions to a minimum and not leaving static secrets in Pods.
Automated TLS: cert-manager. Managing certificates by hand does not scale: they expire and become inconsistent. cert-manager automates the life cycle through CRDs: Issuer and ClusterIssuer (who issues: self-signed, internal CA, ACME/Let's Encrypt, Vault) and Certificate (what to issue, with name, SANs, duration and renewBefore for early renewal). It generates the request, obtains the signature, fills in a Secret with tls.crt and tls.key and renews on its own. The certificate is X.509, part of a chain of trust that ends at a root CA. Kubernetes itself uses more than one CA (etcd, API server, front-proxy) to compartmentalize: if one leaks, the others remain intact.
Secret rotation. Secrets should be changed to reduce the exposure window. An instant swap is impractical in distributed systems (there is no global lock), so a coexistence period is used: the new credential and the old one are valid at the same time until everyone has migrated, and then the old one is invalidated. Dynamic secrets (Vault, short-lived tokens) are already ephemeral and almost dispense with rotation. In the rotation of the etcd encryption key, all API servers need to know the new key *before* it starts being used for writing, otherwise an API server that does not know it cannot read the data written with it.
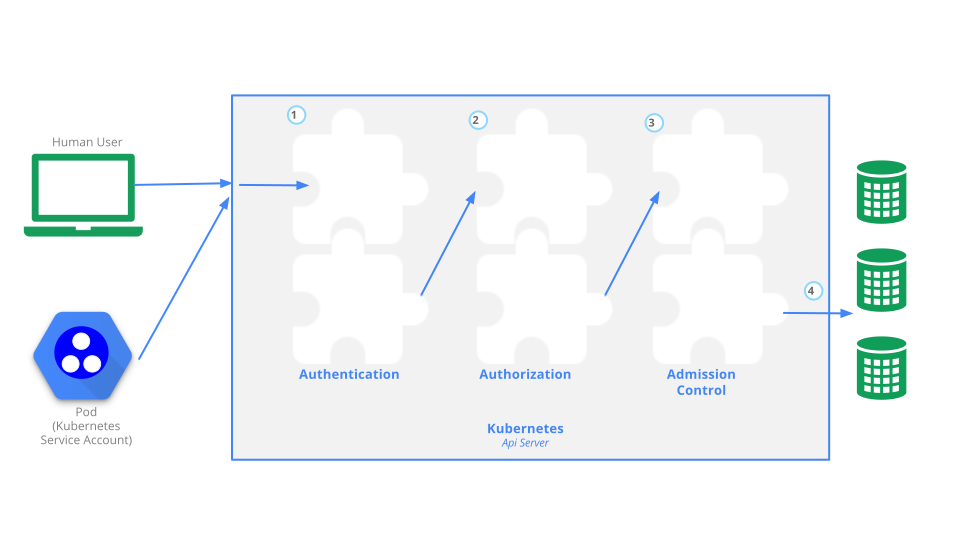
Key concepts
Three pillars
ServiceAccount (identity), RBAC (authorization) and cert-manager (encryption), under Zero Trust.
One ServiceAccount per application
never the default.
Least-privilege RBAC
Role in the namespace, specific verbs and resources, no *.
RBAC is additive and auditable
there are only rules that grant permission; ABAC is legacy; OPA/Gatekeeper covers conditional policies.
Federated identity
IRSA and Workload Identity deliver short-lived credentials, with no static key in the Pod.
cert-manager
Issuer and Certificate automate issuance and renewal; multiple CAs compartmentalize trust.
Rotation with coexistence
the new credential and the old one are valid together until everyone has migrated.
Lessons from incidents
least-privilege IAM and secrets kept out of Pods limit the damage.
Worked examples
RBAC runs on Minikube. The IRSA annotation only takes effect on EKS with the OIDC provider configured, but the YAML is accepted normally by the local cluster, which simply ignores the annotation.
# rbac-analytics.yamlapiVersion: v1kind: ServiceAccountmetadata:name: analytics-sanamespace: analyticsannotations:eks.amazonaws.com/role-arn: arn:aws:iam::123456789012:role/S3Reader # IRSA: only works on EKS; fictitious ARN---apiVersion: rbac.authorization.k8s.io/v1kind: Role # restricted to the namespace, it is not a ClusterRolemetadata:name: analytics-readnamespace: analyticsrules:- apiGroups: [""] # the API's "core" groupresources: ["pods"]verbs: ["get", "list"] # read-only, no "*"- apiGroups: [""]resources: ["configmaps"]verbs: ["get"]---apiVersion: rbac.authorization.k8s.io/v1kind: RoleBindingmetadata:name: bind-analytics-readnamespace: analyticsroleRef: # which RoleapiGroup: rbac.authorization.k8s.iokind: Rolename: analytics-readsubjects: # for whom- kind: ServiceAccountname: analytics-sanamespace: analytics
Essential commands for this stage
Hands-on
- Create the RBAC test environment:
kubectl create namespace lab,kubectl create serviceaccount leitor -n lab,kubectl create role ler-pods --verb=get,list --resource=pods -n labandkubectl create rolebinding bind-leitor --role=ler-pods --serviceaccount=lab:leitor -n lab. - Test with
kubectl auth can-i list pods -n lab --as=system:serviceaccount:lab:leitor. Observeyes. - Test
delete podsandget secrets(which were not granted). Observenoon both. Also testlist pods -n default: observeno, because the Role only applies in the namespacelab. - Apply
rbac-analytics.yaml(after creating the namespaceanalytics) and runkubectl create token analytics-sa -n analytics. Observe that the token is generated on the spot, with limited validity, instead of a permanent credential. - Install cert-manager, apply
pki.yamland runkubectl get certificate. ObserveREADY Trueon both certificates and check withopenssltheissuerof the service's certificate (opensslmust be installed on your machine; without it, usekubectl describe certificate service-a-cert). This demonstrates automatic issuance; renewal happens on its own, at therenewBeforeinterval ahead of expiry. - Read the IRSA example without running it and list what would be missing for it to work (an EKS cluster, an OIDC provider, an IAM Role with the trust relationship with the ServiceAccount).
- Clean up:
kubectl delete namespace lab analytics,kubectl delete -f pki.yaml,kubectl delete secret ca-interna-tls service-a-tls(cert-manager does not delete the Secrets it created by default) andhelm uninstall cert-manager -n cert-manager.
Tip: Use kubectl auth can-i --as=... in CI to validate that your ServiceAccounts have *exactly* the expected permissions and nothing beyond. Combine with minimal-scope IRSA or Workload Identity: that way, even if a container is compromised, the attacker is limited to what that specific identity can do, inside and outside the cluster.
Takeaway: One ServiceAccount per application, RBAC with only the necessary verbs and short-lived credentials turn a compromised container into a contained incident.
Stage 10 bonus · podinfo in production
Bonus, podinfo from the basics module goes to production
The problem
Stage 09 of the basics guide left podinfo working with a ConfigMap, a Deployment of 3 replicas, a NodePort Service and an HPA between 2 and 8 replicas. It works, but it has gaps that the stages of this guide taught you to close. There is a single environment, with the YAMLs copied by hand. The Pod runs with the default ServiceAccount. Nothing guarantees that the replicas will not all land on the same node, and a node drain can take out too many replicas at the same time. The CPU limit can cause throttling in a latency-sensitive service. And there is no way to test a new version without exposing all replicas to it at once.
The concept
This stage turns the manifests from Stage 09 of the basics guide into a Helm chart and reinforces the Deployment with the pieces from this guide. Each piece comes from the stage that taught it:
- Helm (Stage 04): the ConfigMap, the Service and the HPA go into the chart without relevant changes, as templates. The same chart serves dev, staging and production, changing only the values file.
- Minimal ServiceAccount (Stage 09): podinfo gets a ServiceAccount of its own. It is an HTTP server that never calls the API Server, so it receives no Role or RoleBinding, and the token is not even mounted in the Pod (
automountServiceAccountToken: false). It is least privilege taken to the limit: no credential where none is needed. - No CPU limit (Stage 01): podinfo is latency-sensitive, so the chart keeps CPU and memory requests and a memory-only limit, to avoid throttling. The Pod is Burstable.
- Topology Spread (Stage 02): spreads the replicas across nodes with
maxSkew: 1, so that the loss of one node does not take all the replicas. In multi-node production, useDoNotSchedule; on Minikube, with a single node,ScheduleAnyway, becauseDoNotSchedulewould leave the replicas beyond the first inPendingforever. - PodDisruptionBudget (Stage 02): guarantees a floor of replicas during voluntary disruptions (drain, node upgrade, Karpenter consolidation). As seen in Stage 02, it does not protect against eviction under resource pressure.
- Tuned rollout (Stage 03):
maxUnavailable: 0to never reduce capacity,maxSurge: 1to create one extra Pod at a time,minReadySecondsand thechange-causeannotation to record each swap. - Canary (Stage 06): a second release of the same chart, with 1 replica and the new version, receives a fraction of the traffic of the same Service (the native technique by replica ratio). The promotion is a
helm upgrade --atomic.
Why the chart needs to distinguish the canary. Two releases of the same chart cannot create objects with the same name (Helm refuses, because the object belongs to another release). That is why the Deployment's name comes from .Release.Name, and Service, ConfigMap, HPA, ServiceAccount and PDB are only created by the stable release (canary: false). The Pods distinguish the version with a track label (stable or canary), used in the selector of each Deployment, so that two Deployments do not fight over the same Pods. The Service selects only by app: podinfo, so it sees both.
What is left out, and why:
- Karpenter and IRSA or Workload Identity are cloud concepts, with no effect on a single-node Minikube; they stay read-only in Stages 07 and 09.
- cert-manager: with no ingress with TLS in this lab, there is nothing to issue or renew.
- KEDA: the HPA that already exists covers podinfo's profile, an HTTP API that should not go to zero; scale-to-zero by queue makes sense for queue workers.
- Blue/Green: for a single public Service, one promotion strategy is chosen. The canary, progressive and metric-driven, fits better with a service that already exposes
/healthzand/readyz. - PVC: stays out, for the same reason as in the basics guide (a
ReadWriteOncevolume shared among several replicas). - podAntiAffinity: the chart follows the advice of Stage 02 and uses Topology Spread instead of affinity between Pods.
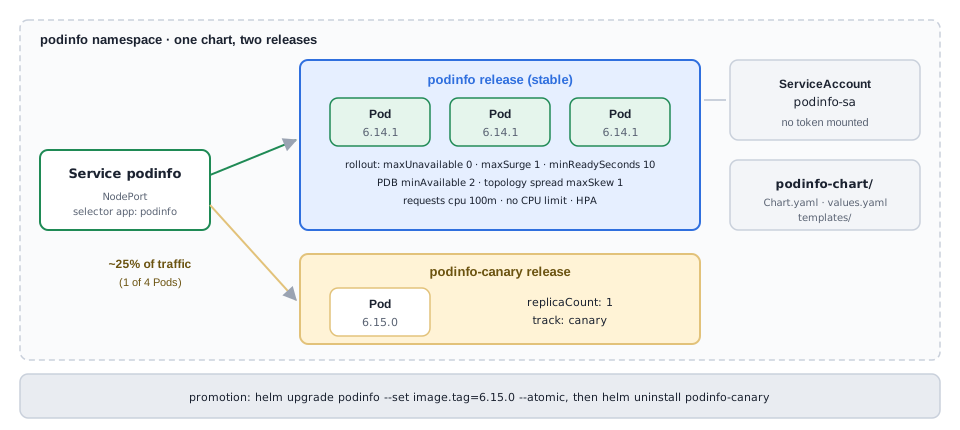
helm upgrade --atomic of the stable release followed by removing the canary.Diagram: made for this guideKey concepts
Helm as the base
one chart, one values file per environment, the same mold for all.
ServiceAccount without permissions
own identity, no Role and no mounted token.
No CPU limit
avoids throttling in a latency-sensitive service; the Pod is Burstable.
Topology Spread with maxSkew: 1
spreads the replicas; ScheduleAnyway on Minikube and DoNotSchedule in multi-node production.
PDB
floor of replicas in voluntary disruptions; it does not apply to eviction under pressure.
Tuned rollout
maxUnavailable: 0, maxSurge: 1, minReadySeconds and change-cause.
Canary by parallel release
second release with label track: canary, same Service, promotion by helm upgrade --atomic.
Worked examples
The folder structure is podinfo-chart/ with Chart.yaml, values.yaml and, inside templates/, six files. The template files below are identified by the name in the comment on the first line.
# Chart.yamlapiVersion: v2name: podinfodescription: podinfo em formato de produçãotype: applicationversion: 0.1.0 # chart versionappVersion: "6.14.1" # application version
Essential commands for this stage
--set values)Hands-on
- Assemble the folder
podinfo-chart/withChart.yaml,values.yamland the six files oftemplates/. Runhelm lint ./podinfo-chartandhelm template podinfo ./podinfo-chartand observe the rendered YAML, with the Deployment, the Service, the HPA, the ServiceAccount and the PDB. - Run
helm template podinfo-canary ./podinfo-chart --set canary=trueand observe that only the Deployment appears as an object (namedpodinfo-canaryand withtrack: canary); the other files appear empty or with only the comment from the first line, under# Source:. This is what avoids name collisions between the two releases. - Check the tags with
docker manifest inspect stefanprodan/podinfo:6.14.1anddocker manifest inspect stefanprodan/podinfo:6.15.0. With both confirmed, install production:helm install podinfo ./podinfo-chart -n podinfo --create-namespace, and confirm 3RunningPods withkubectl get pods -n podinfo -o wide. - Run the three
kubectl auth can-icalls forpodinfo-sa. Observenoon all three: the app has no reason to call the API Server, so it received no credential at all. - Run
kubectl get pdb podinfo -n podinfoand observeALLOWED DISRUPTIONS 1(3 healthy Pods, minimum of 2). - Bring up the canary with
helm install podinfo-canary ... --set canary=true --set replicaCount=1 --set image.tag=6.15.0and observe inkubectl get endpoints podinfo -n podinfothe 4 IPs, one of them with the new version serving real traffic. - Promote with
helm upgrade podinfo ... --set image.tag=6.15.0 --atomic, remove the canary withhelm uninstall podinfo-canary -n podinfoand confirm inkubectl rollout history deployment/podinfo -n podinfothat the swap was recorded. - Clean up both releases: the canary already left in step 7, so run
helm uninstall podinfo -n podinfoandkubectl delete namespace podinfo.
Tip: --atomic is not a complete guarantee: it undoes the release if the probes do not become healthy, but only after trying. Always combine it with the PDB and with maxUnavailable: 0, so that a failed attempt never reduces capacity while Helm is still deciding to give up. Two precisions about the chart: a minAvailable equal to the HPA's minReplicas (2, in this case) leaves ALLOWED DISRUPTIONS at 0 when the HPA is at the floor, and a drain at that moment gets blocked (consider maxUnavailable: 1 in the PDB). And the Deployment's replicas field is reapplied from the chart's value on every helm upgrade, which can undo the HPA's adjustment; a common practice is to omit replicas from the template when the HPA is active.
Takeaway: A production deployment is the right composition and not more YAML: Helm packages, a ServiceAccount without permissions isolates the identity, topology spread and the PDB protect against node failure and maintenance, the tuned rollout avoids a drop in capacity and the canary tests the new version with real traffic.
Stage 11 · review
Self-assessment checklist
Stage 01: Health and resources
- I can say what happens when each probe fails (liveness, readiness, startup).
- I took a Pod out of the Service with
/readyz/disableand confirmed the missing endpoint, with no restart. - I brought down the process with
/panicand can explain that what restarted it was therestartPolicy, not the liveness. - I saw a liveness really fail, with the process alive, and the container being restarted because of it.
- I caused an OOMKill and can explain the difference between exceeding the memory limit and the CPU limit.
- I checked the three QoS classes with
qosClassand know what determines each one. - I can explain why a CPU limit can increase latency.
Stage 02: Scheduling and nodes
- I saw a Pod
Pendingbecause ofuntolerated taintand made it run with toleration and affinity. - I can explain why the taint alone does not guarantee that the Pod goes to the dedicated node.
- I distributed 4 replicas across 2 nodes with
topologySpreadConstraintsandmaxSkew: 1. - I saw a
drainbeing refused by a PodDisruptionBudget and went back to the default cluster after deleting thelabprofile. - I can explain the difference between voluntary and involuntary disruption, and why eviction under resource pressure ignores the PDB and is not an OOMKill.
Stage 03: Rollouts
- I did a rolling update with
maxUnavailable: 0andmaxSurge: 1and observed the pace. - I detected a stalled rollout with
progressDeadlineSecondsand went back withrollout undo. - I recorded the
change-causeand saw it in therollout history. - I can say when to use Recreate instead of RollingUpdate.
Stage 04: Helm
- I created a chart from scratch and rendered it with
helm templateandhelm lint. - I installed, upgraded and rolled back a release, and saw the revision history.
- I saw
--atomicundo an upgrade that did not become healthy. - I can explain the difference between
versionandappVersion.
Stage 05: Blue/Green
- I did the promotion and the rollback with
kubectl patchon the Service's selector. - I can explain why database compatibility is the main risk.
- I can say why the idle environment should only be shut down after stabilizing.
Stage 06: Canary
- I set up a canary by replica ratio and measured the split with 20 requests.
- I can explain the limit of this technique and why a service mesh or Argo Rollouts allow exact weight.
- I can say the difference between Blue/Green and canary.
Stage 07: Karpenter
- I caused a
PendingPod because ofInsufficient cpuand read theFailedSchedulingevent. - I can explain Karpenter's flow (pending Pod, calculation, new node, consolidation).
- I can say why the PDB reduces, but does not eliminate, the risk of a Spot interruption.
Stage 08: KEDA
- I installed KEDA and saw the Deployment go to zero and come up according to the queue.
- I can say what KEDA does that the HPA alone does not do.
- I can explain the condition
λ < c·μand what thecooldownPeriodcontrols. - I can explain why, with an empty queue, the Deployment goes straight from 4 replicas to 0, without waiting for the HPA's 5 minutes of stabilization.
Stage 09: Security
- I created a ServiceAccount with a read-only Role and validated it with
kubectl auth can-i. - I generated a short-lived token with
kubectl create token. - I issued a certificate with cert-manager, checked the issuer with
openssland also deleted the Secrets it created. - I can explain what IRSA and Workload Identity avoid.
Stage 10: Bonus
- I assembled the podinfo chart and rendered the stable and canary releases with
helm template. - I checked podinfo's tags with
docker manifest inspectbefore installing. - I proved with
kubectl auth can-ithat podinfo's ServiceAccount can do nothing. - I brought up the canary, saw 4 endpoints and promoted with
helm upgrade --atomic. - I can explain why the chart needs the
tracklabel and theif not .Values.canaryconditions.
Next steps: with all items checked, redo Stage 10 from scratch without consulting the guide, this time on a multi-node Minikube profile (like the one in Stage 02) and with whenUnsatisfiable: DoNotSchedule, and check the distribution of the replicas with kubectl get pods -o wide. Then, if you have access to a test cloud account, run the snippets that were read-only here: Karpenter's NodePool, IRSA or Workload Identity and the exact-weight canary with Istio or Argo Rollouts.
Teacher's notes: technical precisions
- This block gathers details that help you read the examples safely. Nothing here changes the path of the exercises; they are clarifications about behaviors that tend to raise questions.
- About what you will see in the terminal
- Example outputs: the outputs shown are typical formats. Pod names, ReplicaSet hashes, IPs, ages, columns, event texts and Helm messages vary with the Kubernetes, Minikube and Helm versions. Compare the structure and the behavior, not the exact text. Outputs marked as approximate also depend on your environment's response time.
- `kubectl get endpoints` (Stages 01, 05, 06 and 10): starting with Kubernetes 1.33, the command may display a deprecation warning in favor of EndpointSlices. It remains useful for the exercises; the alternative is
kubectl get endpointslices. - Numbers attributed to companies (Stages 01, 06 and 07): the gains cited for Buffer, Shopify, Netflix, Nubank, Mercado Livre and Tinybird, and Karpenter's savings of up to 30%, are public reports from those companies. They depend on each one's environment and serve as an order of magnitude, not as a promise.
- About behaviors that surprise
- CPU throttling (Stage 01): throttling is the expected behavior of the CFS quota (100 ms periods), not a defect of Kubernetes. A service with short bursts can exhaust the quota of the period and stand still until the next one, even with low average usage. Old kernel versions worsened the effect with flaws that have since been fixed, but the mechanism itself remains.
- QoS classes (Stage 01): Guaranteed requires requests equal to limits in CPU and in memory, in all containers. A Pod with a memory-only limit, like the one in the example, is Burstable.
- Who restarts what (Stage 01): the kubelet recreates containers whose process ended, because of the
restartPolicy, with or without a probe. The liveness exists for the process that stays alive but does not respond. An endpoint that brings the process down (like podinfo's/panic) demonstrates the first case; theliveness-falhaPod demonstrates the second. - Order of eviction (Stage 02): the kubelet evicts first the Pods whose usage of the scarce resource exceeds the request, then considers the priority and, lastly, the usage relative to the request. By default, forced eviction starts with less than 10% free space on the node's filesystem (disk about 90% full) or less than 100Mi of available memory; the values are configurable.
- PDB only applies to voluntary disruption (Stages 02, 07 and 10): the
drain, the node upgrade and Karpenter's consolidation respect the PodDisruptionBudget. Eviction under resource pressure and the removal of a Spot instance by the provider are involuntary and do not wait for the budget. That is why the PDB reduces the risk of a Spot interruption but does not eliminate it. - `kubectl` context (Stage 02):
minikube delete -p labalso deletes thelabcontext. After it, return to the default cluster withminikube startorkubectl config use-context minikubeand confirm withkubectl get nodesbefore moving on. - RollingUpdate percentages (Stage 03): Kubernetes rounds
maxSurgeup andmaxUnavailabledown. With 10 replicas and the 25% defaults, the rollout allows at most 13 Pods running and at least 8 available, and not exactly 125% and 75%. - `--record` is deprecated (Stage 03): to record the reason for a swap, use the
kubernetes.io/change-causeannotation on the Deployment, withkubectl annotateor in the manifest itself. - Helm templates and revisions (Stage 04): a template produces the same YAML for the same values, except when it uses functions such as
lookup,noworrandAlphaNum.helm upgradewithout changes does not alter the cluster's resources, but records a new revision, andhelm rollbackalso creates a new revision instead of erasing the intermediate ones. - Selector switch and open connections (Stage 05): the selector switch applies to new connections. Connections that are already open, such as HTTP keep-alive ones, may stay on the old Pods until they are closed.
- Istio API versions and weight in Argo Rollouts (Stage 06): the
VirtualServiceneeds aDestinationRulethat declares the subsets, and old Istio installations usenetworking.istio.io/v1beta1. In Argo Rollouts, withouttrafficRoutingthesetWeightis approximated by the number of replicas, as in the native technique; only with a compatible router is the weight exact. - `nodeClassRef` in Karpenter (Stage 07): in
karpenter.sh/v1, thenodeClassRefrequiresgroup,kindandname. The cluster, role and tag names in the examples are placeholders. - `cooldownPeriod` and the HPA window in KEDA (Stage 08): the
cooldownPeriodcounts the time with the trigger inactive and only applies to the move to zero, which KEDA does directly, from any number of replicas. The HPA's 5-minute stabilization window applies to reductions with the queue still active. The dead band (different thresholds to go up and down) is a general control concept; the HPA and KEDA use tolerance and windows, not separate thresholds. - RabbitMQ connection in KEDA (Stage 08): the
rabbitmqtrigger needs the connection information for the broker, such ashostFromEnv, read from a variable in the target Deployment's container. Theredis-clioutput in the example shows only numbers becausekubectl execwithout-tdoes not open a terminal. - cert-manager cleanup (Stage 09): cert-manager does not delete the Secrets it created by default. After removing the Certificates, also delete
ca-interna-tlsandservice-a-tls. - RBAC, ABAC and cloud federation (Stage 09): RBAC only has rules that grant permission; to deny by condition, an admission mechanism such as OPA/Gatekeeper is used. ABAC is a legacy mechanism, rarely used. On EKS, EKS Pod Identity is a more recent alternative to IRSA. In the rotation of the etcd encryption key, all API servers need to know the new key before it starts being used for writing.
- Object names in parallel releases (Stage 10): two releases of the same chart cannot create objects with the same name. The chart uses
.Release.Namein the Deployment so that the canary release does not collide with the main one, creates Service, ConfigMap, HPA, ServiceAccount and PDB only in the stable release (canary: false) and uses thetracklabel in the selectors so that the two Deployments do not fight over the same Pods. - `replicas` and PDB with the HPA (Stage 10): the Deployment's
replicasis reapplied from the chart's value on everyhelm upgrade, which can undo the HPA's adjustment; a common practice is to omit it from the template when the HPA is active. Also, aminAvailableequal to the HPA'sminReplicasleavesALLOWED DISRUPTIONSat 0 when the HPA is at the floor, and adrainat that moment gets blocked. - Points to check before running
- Image tags (Stages 01 and 10):
stefanprodan/podinfo:6.14.1and6.15.0were not verified here. Check withdocker manifest inspect stefanprodan/podinfo:<tag>: a JSON indicates the tag exists, andno such manifestindicates it does not. If they do not exist, use published tags. The format of podinfo's response JSON, used in the Stage 10grep, may also vary. - Lab images:
polinux/stress(Stage 01),busybox(Stages 01, 05, 06 and 08),hashicorp/http-echo(Stages 05 and 06),redis:7(Stage 08) andcurlimages/curl(Stage 10) are common public images. Confirm availability at the time of running. - Node names (Stage 02): the Minikube
labprofile names the nodeslabandlab-m02. If your environment uses other names, adjust the taint, label and drain commands.